Holy Sh*t I Think Anthropic Is Profitable Now
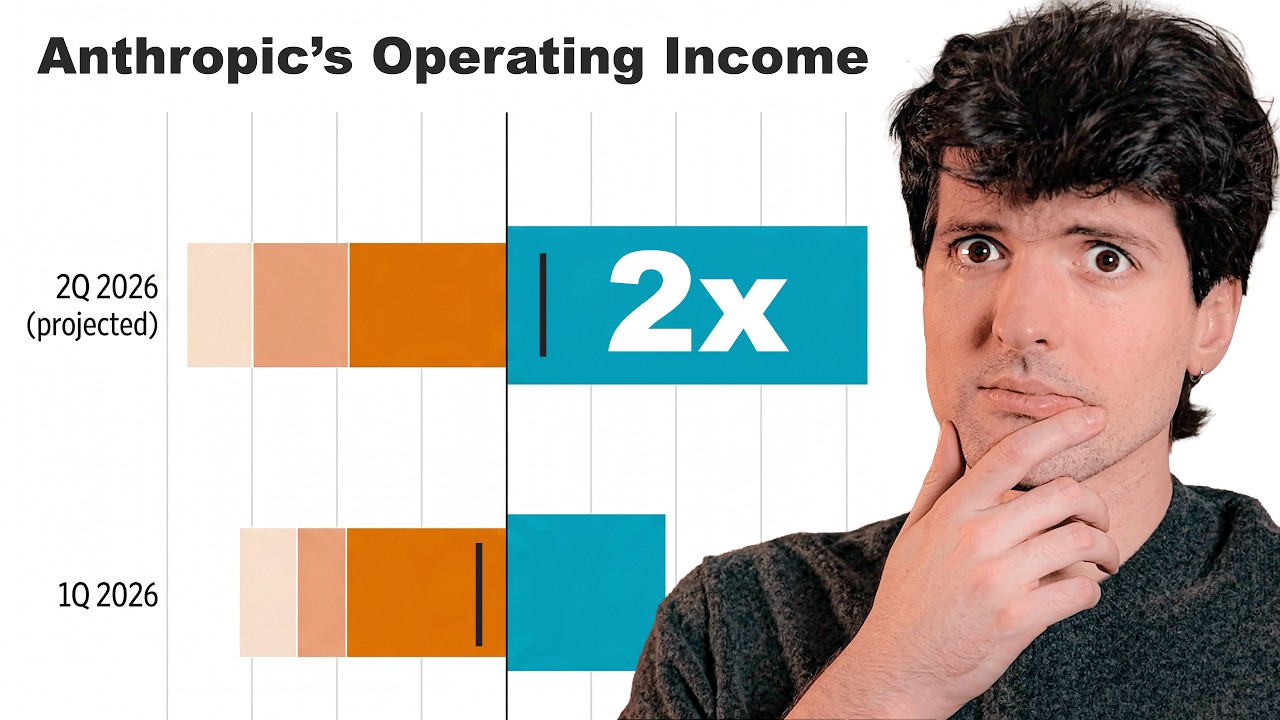
🔗 **Source:** [Holy Sh*t I Think Anthropic Is Profitable Now](https://www.youtube.com/watch?v=q88yYhLSPC0)
> [!note]+ Document Notes
> tags: [ai-profitability, enterprise-ai, anthropic, cloud-infrastructure, ai-pricing]
> author: Theo
> source: Theo - t3.gg
> reference: https://www.youtube.com/watch?v=q88yYhLSPC0
> date created: {{date:YYYY-MM-DD}} {{time:HH:mm}}
>
> # 🏷️ Title: Holy sh*t I think Anthropic is profitable now
>
<!-- deep-read:sections start -->
## 🧭 Table of Contents
- [📝 Summary](#-summary)
- [📖 Main Content](#-main-content)
- [🗒️ Notes](#️-notes)
- [📚 References](#-references)
- [🗣️ Paraphrase](#️-paraphrase)
- [📰 Newsletter](#-newsletter)
- [✅ Action Items](#-action-items)
- [🧪 Hypotheses](#-hypotheses)
- [📊 Methodology](#-methodology)
- [❓ Questions](#-questions)
- [🔮 Future Research](#-future-research)
- [💡 Implications](#-implications)
- [🧠 Learning Styles Assessment](#-learning-styles-assessment)
- [📊 Accessibility Assessment](#-accessibility-assessment)
- [🌍 DEIB Assessment](#-deib-assessment)
- [✅ Logical Validity](#-logical-validity)
- [🛡️ DARVO Analysis](#-darvo-analysis)
- [🎯 Conclusion](#-conclusion)
## 📝 Summary
- **What happened**: Anthropic reported its first profitable quarter with $10.9B revenue and 15x valuation growth from $60B to $900B in 14 months.
- **Why it matters**: First major AI lab to achieve profitability, signaling potential product-market fit for enterprise AI tools.
- **Key stakeholders**: Anthropic, OpenAI, AWS/Google Cloud, enterprise customers paying dramatically higher AI bills.
- **Risks and tradeoffs**: Aggressive pricing increases (3x costs in real usage), potential customer churn, dependency on cloud partnerships.
- **Bottom line**: Success driven by AWS exclusivity, Claude Opus 4.5 breakthrough, strategic price increases, and enterprise willingness to pay premium for quality AI.
## 📖 Main Content
Anthropic's path to profitability represents a fundamental shift in the AI industry from growth-at-all-costs to sustainable revenue models. The company achieved this through several strategic advantages and market positioning moves.
### Cloud Distribution Advantage
Unlike OpenAI, which is primarily available through Microsoft Azure, Anthropic models are accessible across all major cloud platforms (AWS, Google Cloud, Azure). This multi-cloud strategy is crucial because AWS powers 90% of Fortune 100 companies. Enterprise customers prefer using AI models within their existing cloud infrastructure rather than switching platforms.
### Pricing Strategy Evolution
Anthropic implemented a sophisticated pricing restructure disguised as model improvements. While Opus pricing appeared to decrease from $75 to $25 per million output tokens, they actually shifted the model tiers rightward - making Opus 4.5 replace Sonnet's role at higher pricing ($15 to $25 per million tokens for most users' primary model).
### Technical Changes Increasing Costs
The new tokenizer in Claude 4.7 creates 30-50% more tokens from the same text, effectively increasing costs by that percentage. Additionally, incorrect AI responses generate significantly more tokens (potentially millions vs. thousands), creating expensive failure modes for customers.
### Enterprise Sales Pivot
Both companies shifted from consumer subscription models to enterprise API pricing. Personal tier users might get $1,000+ worth of API usage for $100-200 monthly subscriptions, but enterprises now pay full API rates plus seat fees, dramatically increasing revenue per customer.
## 🗒️ Notes
#### ⏱️ [00:01:25](https://www.youtube.com/watch?v=q88yYhLSPC0&t=85) Anthropic's Revenue Growth Timeline
- 14 months ago: $60B valuation
- Current round: $900B valuation (15x growth)
- 2024 start: $87M annual revenue
- End of year: $1B revenue
- Recent: $30B quarterly revenue
#### ⏱️ [00:04:12](https://www.youtube.com/watch?v=q88yYhLSPC0&t=252) AWS Partnership Advantage
- AWS powers 90%+ of Fortune 100 companies
- Anthropic only viable enterprise AI option on AWS
- OpenAI limited to Azure (less enterprise adoption)
- Multi-cloud availability (AWS, GCP, Azure) vs. OpenAI's single cloud
#### ⏱️ [00:07:30](https://www.youtube.com/watch?v=q88yYhLSPC0&t=450) Compute Resource Competition
- Researchers prefer NVIDIA GPUs over AWS Tranium/Google TPUs
- Claude Code users compete with researchers for GPU access
- Usage limitations implemented to preserve research compute
- Revenue sharing deals with clouds (≈50% fee per token)
#### ⏱️ [00:11:45](https://www.youtube.com/watch?v=q88yYhLSPC0&t=705) Pricing Model Restructure
- Previous tiers: Haiku (cheap) → Sonnet (reasonable) → Opus (expensive)
- New reality: Haiku (wasteful) → Opus 4.5 (premium Sonnet replacement) → Mythos (unavailable)
- Effective price increase from $15 to $25 per million tokens for primary use cases
#### ⏱️ [00:14:20](https://www.youtube.com/watch?v=q88yYhLSPC0&t=860) Tokenization Cost Inflation
- Claude 4.7 tokenizer creates 30-50% more tokens
- Wrong answers cost exponentially more (thousands vs. millions of tokens)
- Opus 4.7: 100K tokens average vs. GPT-4: 67K tokens for same tasks
- Real-world cost increase: $4.70 → $16 per coding task
#### ⏱️ [00:18:45](https://www.youtube.com/watch?v=q88yYhLSPC0&t=1125) Enterprise Sales Transformation
- 30% of OpenAI jobs (703 total) in enterprise sales
- 27% of Anthropic jobs (390 total) in enterprise sales
- Enterprise customers now pay API rates + seat fees
- Personal tier users still subsidized ($200 plan = $1000+ API value)
#### ⏱️ [00:21:30](https://www.youtube.com/watch?v=q88yYhLSPC0&t=1290) Product-Market Fit Evidence
- Companies paying despite 3x cost increases
- Claude Opus 4.5 as breakthrough model
- Enterprise budget overruns (Uber: full year budget in 3 months)
- Minimal discounts even for $40K/month commitments
## 📚 References
- [TechCrunch article on Anthropic profitability](https://techcrunch.com)
- [Simon Willis PMF analysis](https://simonwillison.net)
- [AWS market share data](#)
- [DeepSW SWE benchmark results](#)
## 🗣️ Paraphrase
Anthropic achieved its first profitable quarter through a combination of strategic advantages and market timing rather than pure technical superiority. Their multi-cloud distribution strategy, particularly their exclusive position as the premium AI option on AWS, gave them access to enterprise customers that OpenAI couldn't reach through Azure alone.
The company implemented clever pricing changes that appeared to reduce costs while actually increasing them for most users. They restructured their model tiers and introduced a new tokenizer that generates more tokens, effectively raising prices while marketing improvements.
Most importantly, Claude Opus 4.5 represented a genuine capability breakthrough that convinced enterprise customers AI could handle complex, real-world tasks. This created demand inelastic enough that companies continue paying despite dramatic cost increases, suggesting genuine product-market fit in the enterprise segment.
## 📰 Newsletter
**🚀 AI Profitability Milestone: What Anthropic's Success Means for WordPress Developers**
Anthropic just hit their first profitable quarter with $10.9B revenue - a massive milestone for the AI industry! While OpenAI burns cash, Anthropic cracked the code through smart cloud partnerships and enterprise pricing.
**Key takeaways for our community:**
- **Multi-platform strategy wins**: Anthropic's availability across AWS, Google Cloud, and Azure vs. OpenAI's Azure lock-in shows the power of platform diversity
- **Enterprise AI adoption is real**: Companies are spending $200+ per user monthly on AI tools, validating the enterprise AI market
- **Pricing power from quality**: When your product genuinely solves problems, customers will pay premium rates (even 3x increases!)
**WordPress implications:**
- Expect more AI-powered plugins and tools as enterprise adoption validates the market
- Consider multi-platform strategies for your own SaaS products
- Quality differentiation matters more than price competition in emerging markets
The era of "AI as a feature" is evolving into "AI as core infrastructure." Time to think about how this affects your development workflow and business strategy!
[Read the full analysis](https://www.youtube.com/watch?v=q88yYhLSPC0)
## ✅ Action Items
#### DevRel
- Research Anthropic's developer experience strategy vs. OpenAI's approach
- Analyze multi-cloud AI model deployment patterns for developer education content
- Create cost comparison guides for AI model usage in development workflows
- Document enterprise AI adoption patterns for developer advocacy materials
#### Community
- Survey WordPress developers on AI tool usage and cost tolerance
- Create AI model selection guides for different use cases and budgets
- Host discussions on enterprise AI strategy for agencies and consultants
#### WordPress
- **Core AI**: Evaluate Anthropic models for core WordPress AI features given their enterprise focus
- **Plugin Directory**: Monitor AI-powered plugin submissions and cost models
- **Developer Tools**: Consider multi-cloud AI integrations for official tooling
## 🧪 Hypotheses
- Enterprise willingness to pay premium AI pricing indicates sustainable B2B market for AI-powered WordPress tools
- Multi-cloud AI model availability correlates with higher enterprise adoption rates
- AI model quality improvements justify 3x cost increases when productivity gains are measurable
- Cloud platform partnerships are more valuable than direct customer acquisition for AI companies
- Tokenization changes can effectively implement price increases while appearing to offer improvements
- Enterprise AI sales require significant human sales teams despite being AI companies
### 📊 Methodology
- Compare enterprise adoption rates across single-cloud vs. multi-cloud AI providers
- Analyze correlation between AI model benchmark scores and pricing power
- Survey enterprise customers on price sensitivity vs. quality trade-offs
- Track conversion rates from personal AI subscriptions to enterprise contracts
- Measure productivity gains vs. cost increases in real enterprise environments
### ❓ Questions
- How sustainable are 3x price increases once competitors achieve similar model quality?
- Will enterprise customers develop multi-vendor AI strategies to avoid lock-in?
- How do cloud partnerships affect AI model performance and availability?
- What percentage of Anthropic's profit comes from AWS revenue sharing vs. direct sales?
- How quickly can OpenAI replicate Anthropic's multi-cloud distribution advantage?
### 🔮 Future Research
- Long-term sustainability of enterprise AI pricing models
- Impact of model quality improvements on customer retention vs. acquisition
- Role of cloud partnerships in AI company valuations and exit strategies
- Enterprise AI budget allocation patterns and decision-making processes
### 💡 Implications
- **Practice**: WordPress developers should expect AI tools to become core infrastructure costs, not optional features
- **Policy**: Multi-cloud AI availability may become a competitive requirement for enterprise software
- **Security**: Enterprise AI adoption validates need for robust AI governance and cost management tools
- **Education**: Developer training should include AI cost optimization and multi-model strategies
- **Funding**: AI company valuations may shift from user growth to enterprise revenue metrics
### 🧠 Learning Styles Assessment
Reading level estimate: 12th grade (Flesch-Kincaid)
#### 👀 Visual learners
- Present: Revenue growth charts, model tier diagrams, cost comparison tables
- Improve: Add AWS market share visualization, tokenization impact flowcharts, enterprise adoption timelines
#### 🔊 Aural learners
- Present: Video format with detailed verbal explanations
- Improve: Create 5-minute audio summary of key business model insights
#### 🗣️ Verbal learners
- Present: Clear analogies (GPU preferences, tier shifting strategy), defined technical terms
- Improve: Add glossary for AI/cloud terms, more business model analogies
#### 🧩 Kinesthetic learners
- Present: Step-by-step pricing analysis, actionable takeaways
- Improve: Create cost calculator tool, hands-on AI model comparison exercises
#### 🧠 Logical learners
- Present: Clear cause-effect relationships, revenue calculations, strategic decision trees
- Improve: Add quantitative analysis framework, logical argument mapping
#### 🧑🤝🧑 Social learners
- Present: Discussion prompts about enterprise adoption
- Improve: Add community discussion questions, peer comparison opportunities
#### 🧘♀️ Solitary learners
- Present: Self-contained analysis with clear conclusions
- Improve: Add reflection questions on implications for individual practice
#### 🌿 Naturalistic learners
- Present: Business ecosystem analogies
- Improve: Connect to broader technology adoption lifecycle patterns
### 📊 Accessibility Assessment
#### Screen reader semantics
- Present: Clear heading structure, descriptive video content
- Improve: Add alt text for timestamp references, enhance heading descriptions
#### Keyboard navigation
- Present: Standard YouTube video controls
- Improve: Provide transcript with searchable timestamps
#### Contrast and readability
- Present: Clear text analysis
- Improve: Verify technical term readability, avoid low-contrast code examples
#### Text resizing and reflow
- Present: Responsive text analysis
- Improve: Ensure timestamp links work at high zoom levels
#### Media and captions
- Present: Video with transcript
- Improve: Verify caption accuracy for technical terms, add downloadable transcript
#### Forms and interactions
- Present: Simple link navigation
- Improve: Ensure YouTube embeds are keyboard accessible
### 🌍 DEIB Assessment
#### Cultural breadth
- Present: US-focused enterprise analysis
- Improve: Include global cloud adoption patterns, international AI regulations
#### Inclusive language
- Present: Technical business analysis
- Improve: Define enterprise sales jargon, avoid Silicon Valley insider terms
#### Neurodiversity support
- Present: Clear section structure, consistent analysis format
- Improve: Add executive summary, reduce rapid topic switching
#### Representation
- Present: Focus on business strategy over personalities
- Improve: Include diverse enterprise customer examples, varied company sizes
#### Psychological safety
- Present: Analytical tone focused on business strategy
- Improve: Add content warning for strong language in embedded video content
### ✅ Logical Validity
#### Strong reasoning
- **Causal analysis** (00:04:12): AWS market dominance → enterprise AI adoption. Strong because it connects documented market share data to logical customer preference for existing infrastructure.
- **Economic reasoning** (00:11:45): Model tier restructuring as disguised price increase. Strong deductive logic showing how apparent price cuts actually increased costs for typical users.
- **Market analysis** (00:21:30): Customer retention despite price increases as PMF evidence. Strong inductive reasoning from multiple enterprise spending examples.
#### Fallacies
- **Hasty generalization** (00:18:45): Concluding all AI companies found PMF based on Anthropic's single profitable quarter. Fix: Specify this applies to Anthropic specifically, note OpenAI's different trajectory.
- **Post hoc reasoning** (00:14:20): Assuming all revenue growth comes from pricing changes vs. customer growth. Fix: Acknowledge multiple contributing factors and their relative weights.
#### Tone of voice
- **Analytical but conversational**: "It makes all the sense in the world that their revenue has gone up so fast" - confident assessment with accessible explanation
- **Slightly irreverent**: Technical analysis mixed with casual observations about enterprise sales culture
### 🛡️ DARVO Analysis
No DARVO patterns detected. The analysis focuses on business strategy and market dynamics rather than interpersonal conflict or accountability issues. The content maintains analytical objectivity about competitive dynamics between AI companies.
## 🎯 Conclusion
Anthropic's profitability milestone represents a fundamental shift in AI business models from growth-focused to revenue-sustainable strategies. Their success stems from strategic positioning (multi-cloud availability), product excellence (Claude Opus 4.5), and market timing rather than just technical superiority.
**Practical next steps for readers:**
- Evaluate AI tool costs in your development budget planning
- Consider multi-platform strategies for your own SaaS products
- Monitor enterprise AI adoption patterns in your industry
- Prepare for AI costs becoming core infrastructure expenses rather than optional tools
The transition from "AI as experiment" to "AI as essential infrastructure" is accelerating faster than anticipated, with significant implications for both individual developers and enterprise technology strategies.
## 🔄 Refactor Appendix — Holy sh*t I think Anthropic is profitable now
> Density: 3 Literature atoms, 2 Permanent candidates.
>
> Konik claim-header rules: present tense, declarative, ≤10 words,
> searchable, unique, mirrors annotation focus.
>
> Tag pool: #bmf · #addendum · #xref · #articleseed · #storystem · #share · #aphorisms
### 📚 Literature Atoms (H3)
#### Multi-cloud distribution creates enterprise AI competitive advantage
> [!quote] ID:rw_anthropic_aws
> Unlike OpenAI, anthropic models are hostable on AWS. In fact, they're the only reasonable model option you have on AWS... AWS is powering more than 90% of Fortune 100 companies
**Context & use**:
- 00:04:12 in video analysis of cloud market positioning
- Explains why Anthropic gained enterprise traction despite OpenAI's technical leadership
**Tags**: #xref #articleseed
**Highlight**: [view highlight](https://www.youtube.com/watch?v=q88yYhLSPC0&t=252)
<!-- atomicity: 1 idea ✓ -->
#### Model tier restructuring disguises effective price increases
> [!quote] ID:rw_pricing_tiers
> They just shifted the descriptions to the right... Opus45 didn't replace Opus 41. Opus 45 replaced Sonnet. So, it's actually a price increase. They went from $15 per mill out to $25 per mill out
**Context & use**:
- 00:11:45 analysis of Anthropic's pricing strategy evolution
- Demonstrates how apparent improvements can mask cost increases
**Tags**: #xref #articleseed
**Highlight**: [view highlight](https://www.youtube.com/watch?v=q88yYhLSPC0&t=705)
<!-- atomicity: 1 idea ✓ -->
#### Enterprise customers pay premium rates despite dramatic cost increases
> [!quote] ID:rw_pmf_evidence
> Companies are spending over $200 per month per user... they're not losing customers because the prices went up. In fact, companies are spending more and doing more with them
**Context & use**:
- 00:21:30 discussion of product-market fit evidence
- Shows inelastic demand as proof of genuine value creation
**Tags**: #xref #addendum
**Highlight**: [view highlight](https://www.youtube.com/watch?v=q88yYhLSPC0&t=1290)
<!-- atomicity: 1 idea ✓ -->
### 🧠 Permanent Candidates (H4)
#### Product-market fit enables aggressive pricing power
**Claim**: When enterprise software genuinely solves critical problems, customers will absorb significant cost increases rather than lose the productivity gains.
**Evidence pointer**: [[#Enterprise customers pay premium rates despite dramatic cost increases]]
**Scope & conditions**: Applies when switching costs are high, alternatives are inferior, and productivity impact is measurable. Breaks when competitive alternatives emerge or economic conditions force budget cuts.
**Links**:
- [[Enterprise software pricing strategy]] — because extends
- [[SaaS customer retention factors]] — because evidence-for
<!-- atomicity: 1 idea ✓ -->
#### Multi-platform distribution strategy beats single-platform optimization
**Claim**: Technology companies achieve better enterprise penetration through multi-platform availability than platform-exclusive partnerships, even when the exclusive platform offers better terms.
**Evidence pointer**: [[#Multi-cloud distribution creates enterprise AI competitive advantage]]
**Scope & conditions**: Holds when enterprise customers have strong existing platform preferences and switching costs. May not apply to consumer markets or when platform integration creates significant technical advantages.
**Links**:
- [[Platform strategy trade-offs]] — because contrasts
- [[Enterprise technology adoption patterns]] — because applies-in
<!-- atomicity: 1 idea ✓ -->
### ✏️ Fleeting Queue
- [F1] Research AWS vs Azure enterprise market share data for developer content #fleeting #inbox
- [F2] Investigate WordPress plugin pricing models for AI-powered features #fleeting #inbox
- [F3] Track OpenAI's multi-cloud expansion timeline and strategy #fleeting #inbox
### → Things 3 (max 2 actions)
- [ ] Create AI model cost comparison guide for WordPress developers — enterprise focus #things
- [ ] Survey community on AI tool budget allocation and cost sensitivity #things
---
## Full Transcript
[00:00] The AI bubble is a little bit chaotic.<br>[00:02] There's all of these companies that are<br>[00:03] building things that people spend<br>[00:04] billions of dollars on, but then they<br>[00:06] spend billions more doing it and hosting<br>[00:08] it and they just don't make any money.<br>[00:10] How is this ever going to work out?<br>[00:11] Especially when they're all racing to go<br>[00:13] do their IPO and actually sell stock.<br>[00:15] You need to make money in order to do<br>[00:16] those types of things. And none of these<br>[00:18] companies are even close to profitable.<br>[00:20] Most of them are losing billions of<br>[00:21] dollars every quarter. Just like<br>[00:23] Anthropic, who is uh wait, Anthropic<br>[00:26] says it's about to have its first<br>[00:28] profitable quarter. Anthropic told<br>[00:31] investors that they will more than<br>[00:32] double revenue to around 10.9 billion in<br>[00:35] their second quarter and deliver an<br>[00:36] operating profit for the first time. Oh,<br>[00:40] that's different. I didn't think we<br>[00:42] would get here so fast if I'm being real<br>[00:44] with you guys. I've talked about this<br>[00:46] many times before, comparing the rates<br>[00:48] of growth of revenue against the rates<br>[00:50] of growth of expenses for these<br>[00:52] companies, and I thought the gap would<br>[00:54] get worse before it started to get<br>[00:55] better, much less to hear. There's a lot<br>[00:58] to dive into from how Anthropic got to<br>[01:01] this point, what they are spending their<br>[01:02] money on versus how they're making so<br>[01:04] much money. Where does OpenAI fit in<br>[01:06] here? Are they profitable? Are they<br>[01:07] losing money? How much is Anthropic<br>[01:09] spend going to go straight to SpaceX and<br>[01:11] XAI with their whole Colossus data<br>[01:13] centers? Is this product market fit?<br>[01:15] There's a lot to talk about here and I<br>[01:17] can't wait to do it. But unlike<br>[01:19] Anthropic, I can't just burn cash for my<br>[01:21] team. So, we're going to do a quick<br>[01:22] break for today's sponsor. You know how<br>[01:24] most devs just kind of hate using GUIs<br>[01:26] when they could be using the terminal<br>[01:27] instead? Turns out a lot of normal<br>[01:29] people are like this, too. If they can<br>[01:30] avoid apps in just text, they prefer it.<br>[01:32] But how do you actually integrate that<br>[01:34] in your apps? Wouldn't it be great if<br>[01:35] there was a simple npm package that let<br>[01:37] you send SMS, RCS, and WhatsApp<br>[01:39] messages? That would be pretty great,<br>[01:41] wouldn't it? Oh, it's on my screen,<br>[01:43] isn't it? As soon as I heard about these<br>[01:45] guys, I started playing with it and fell<br>[01:47] in love immediately. It's hilarious how<br>[01:49] much easier it is to use what they built<br>[01:51] than anything I've used before. They<br>[01:53] have SDKs for pretty much everything.<br>[01:54] We're a TypeScript house, so I'm going<br>[01:56] to show you with this. You install their<br>[01:58] package, you create a client, you pass<br>[02:00] the phone number you want to send the<br>[02:01] thing to, and then the template you want<br>[02:03] to use as you send it if you have<br>[02:05] templates already configured in their<br>[02:06] servers. Couldn't be easier. They even<br>[02:08] have a oneline test mode so you can test<br>[02:10] these functionalities without actually<br>[02:12] sending the messages. You'll just see<br>[02:13] them in their dashboard. It's so<br>[02:14] helpful. I don't know how to properly<br>[02:16] emphasize how hilariously simple this<br>[02:18] is. We're talking five lines of code for<br>[02:21] something that used to take so much more<br>[02:23] effort. You might be questioning how do<br>[02:25] you choose to send SMS versus RCS versus<br>[02:27] WhatsApp. You don't have to. They figure<br>[02:29] out what the best solution is for that<br>[02:31] user. Your customer puts in a phone<br>[02:33] number and the rest is done. Their<br>[02:34] preferences are met. You're looking for<br>[02:35] a simple, safe, scalable, and reliable<br>[02:37] solution to communicating with your<br>[02:39] users via phone number? Look no further<br>[02:40] than soy.<br>[02:42] God, the history of their raises is<br>[02:45] absurd. Just 14 months ago, they raised<br>[02:48] at a 61 billion valuation. So, the whole<br>[02:51] company worth 60 bill. Since then, the<br>[02:54] most recent round that they're raising<br>[02:56] right now appears to be at a $900<br>[02:58] billion valuation. 15x in 14 months.<br>[03:02] That is absurd. This might be the<br>[03:04] fastest growth in the history of<br>[03:06] enterprise ever. The difference between<br>[03:08] 60 billion and $900 billion is roughly<br>[03:10] $900 billion. It's kind of crazy. This<br>[03:13] new round they're raising is in the 30<br>[03:15] to 50 bill range against that 900 bill<br>[03:18] val, which is insane when you consider<br>[03:19] they're about to raise almost as much<br>[03:21] money as they were worth a year ago. And<br>[03:23] it's going to be less than 10% of their<br>[03:25] company being diluted through that.<br>[03:27] Truly absurd. But there's a reason why.<br>[03:29] This is the revenue over time in a log<br>[03:31] scaled chart. In 2024, they were doing<br>[03:34] 87 million a year rev. By end of year,<br>[03:37] they had gone up to a bill. By end of<br>[03:39] last year, they were up to nine. And<br>[03:41] since end of 2025 to now, they have<br>[03:43] tripled the 30 bill and rev. This is<br>[03:46] insane. But when you compare this to how<br>[03:48] much money they have to spend even on<br>[03:50] just compute, it gets a lot less crazy.<br>[03:53] They just signed a deal with SpaceX<br>[03:55] where they're doing 1.25 25 bill per<br>[03:57] month in compute with just one of their<br>[04:00] sources. Truly absurd. So their spend is<br>[04:03] insane. But when they're doing 11<br>[04:06] billion per quarter of revenue, those<br>[04:08] costs feel a lot smaller. This<br>[04:10] TechCrunch article is junk. If you think<br>[04:12] their growth is because pros have<br>[04:14] expressed a preference for their chatbot<br>[04:16] or because law firms are starting to<br>[04:18] look into anthropic stuff, you have no<br>[04:20] idea what's happening here. So what<br>[04:22] exactly resulted in anthropic profiting?<br>[04:25] There's layers to this one. The first<br>[04:28] piece I really want to emphasize, it's<br>[04:30] three letters, AWS. I am regularly<br>[04:33] surprised how many people don't<br>[04:34] understand the value of these three<br>[04:36] letters here because unlike OpenAI,<br>[04:39] anthropic models are hostable on AWS. In<br>[04:42] fact, they're the only reasonable model<br>[04:44] option you have on AWS. Obviously, if I<br>[04:47] have the choice between an anthropic<br>[04:48] model and an OpenAI model, I tend to<br>[04:50] lean OpenAI. But if my options are a<br>[04:52] bunch of crappy openweight models, some<br>[04:53] even worse Amazon Nova models, or Opus<br>[04:56] 47, you bet your ass I'm picking Opus.<br>[04:59] AWS is powering more than 90% of Fortune<br>[05:02] 100 companies and between 60 to 80% of<br>[05:05] Fortune 500. While Azure is technically<br>[05:08] 95%, most of that is because of<br>[05:10] Microsoft 365, not actually because of<br>[05:12] Azure compute. I do happen to know that<br>[05:14] Azure's revenue is comparable to AWS<br>[05:17] because they mark a ton of stuff up and<br>[05:18] they have crazy licensing deals and [ __ ]<br>[05:20] combined with 365. They do numbers like<br>[05:24] Azure makes money, but the size of the<br>[05:26] markets here is meaningfully different.<br>[05:27] AWS is about 30% of the market and<br>[05:30] supposedly Azure has 20%. There are very<br>[05:32] few reliable numbers for all of this,<br>[05:35] but I will say with 100% confidence that<br>[05:37] the companies that care about using the<br>[05:39] best stuff, they're all on AWS. When it<br>[05:42] comes to everything from government<br>[05:44] contracts to security platforms to<br>[05:47] building compute in the way that big<br>[05:49] businesses want to, AWS is still very<br>[05:52] much a market leader. And when you think<br>[05:54] about Fortune 500 companies that want to<br>[05:56] adopt AI and developers who want to use<br>[05:58] it at those companies, do you honestly<br>[06:00] think those guys are using Azure and<br>[06:03] Microsoft 365 or do you think they're<br>[06:05] using AWS? Let's be realistic here. I am<br>[06:07] biased here because my enterprise<br>[06:09] experience was in an AWS company that<br>[06:12] very much use AWS stuff. But I don't<br>[06:14] really know many engineers that are<br>[06:16] choosing to build on Azure and very many<br>[06:18] companies that are on there for any<br>[06:19] reason other than being on legacy [ __ ]<br>[06:22] The companies that like legacy [ __ ] tend<br>[06:23] to be on Azure more so than AWS. So when<br>[06:26] we talk about the spend for AI, there's<br>[06:29] a huge benefit to Anthropic that AWS has<br>[06:32] their models. It is also worth noting<br>[06:34] that Anthropic's models are also on GCP<br>[06:37] and Google has a huge investment in<br>[06:38] Anthropic as well as recently on Azure.<br>[06:41] Even though Azure doesn't host them yet,<br>[06:42] Azure just reroutes to the official<br>[06:44] Anthropic hosting. All three clouds<br>[06:47] offer anthropic models. OpenAI models<br>[06:49] are only on the worst option, Azure. And<br>[06:52] it also sucks to run open AAI models on<br>[06:54] as I have been the loudest advocate of<br>[06:56] for a while now. So real companies<br>[06:59] building with AI in their real clouds<br>[07:02] kind of only had one option and it was<br>[07:04] anthropic. So it makes a lot of sense<br>[07:06] that regardless of what cloud you're on,<br>[07:08] anthropic models were a really<br>[07:09] compelling option. So we have the cloud<br>[07:11] advantage. Anthropic models are<br>[07:13] available all of the places these<br>[07:14] companies are. And Anthropic also has<br>[07:16] crazy deals with these clouds where they<br>[07:18] get huge revenue shares even though<br>[07:20] they're not providing the compute. It's<br>[07:22] a great deal for Anthropic. They put<br>[07:24] zero dollars on the line. They give them<br>[07:25] zero compute. They don't allocate<br>[07:27] anything. They just send the weights to<br>[07:29] Google and AWS under crazy agreements of<br>[07:31] like they can't use them for other<br>[07:32] things and then let them host it. But<br>[07:34] they take a 50% fee or so of every<br>[07:37] single token sent. is a huge profit farm<br>[07:40] for Anthropic and it allows them to<br>[07:42] reserve their compute for the things<br>[07:43] they want to do like research. But<br>[07:46] that's where the next section comes in.<br>[07:47] The researchers at Anthropic want their<br>[07:49] GPUs. They really want their GPUs and<br>[07:51] historically they've been able to use<br>[07:53] them because most people would use<br>[07:54] anthropic models through other providers<br>[07:56] like AWS and Google. But then something<br>[07:59] important happened. Claude Code. Cloud<br>[08:02] code in particular when they added<br>[08:03] subscriptions became a huge farm for<br>[08:06] inference for customers that were<br>[08:07] becoming big fans of Anthropic.<br>[08:09] Anthropic needs those customers because<br>[08:11] they will bring their love of cloud code<br>[08:12] to their workplace and then get them to<br>[08:14] spend a shitload of money to give a<br>[08:15] bunch of revenue to Anthropic. But the<br>[08:17] Cloud Code users weren't routing through<br>[08:19] AWS for their own personal use. They<br>[08:22] were routing through Anthropics APIs<br>[08:23] using Anthropics GPUs, which means they<br>[08:26] were competing with the researchers. The<br>[08:27] researchers did not like that. They did<br>[08:29] have pretty big deals with AWS for<br>[08:31] tranium chips as well as GCP for their<br>[08:34] TPUs, but the researchers didn't want<br>[08:36] that. This video is the funniest example<br>[08:39] of how researchers feel about TPUs and<br>[08:43] in particular Tranium from AWS in<br>[08:45] comparison to the GPUs they want with<br>[08:46] Nvidia. This video is absolutely<br>[08:48] hilarious. Huge credit to Tite Fem for<br>[08:50] making it. It's It's so good.<br>[08:52] >> [ __ ] you, San Francisco. If you're dumb<br>[08:54] enough to NEED TWO GIGAWATTS OF COMPUTE<br>[08:56] THIS WEEKEND, YOU'RE A BIG ENOUGH<br>[08:57] SCHMUCK TO COME TO BIG CHEST TRANIUM<br>[08:58] HELL, BAD CHIPS, CLUSTERS THAT BREAK<br>[09:01] DOWN, OVERHEATING. If you think you're<br>[09:02] going to find a bargain ON ML COMPUTE,<br>[09:04] YOU CAN KISS MY ASS. It's our belief<br>[09:06] that you're such a stupid [ __ ]<br>[09:08] you'll fall for this [ __ ]<br>[09:09] Guaranteed. If you find better in<br>[09:11] performance anywhere else, shove it up<br>[09:13] your ugly ass. YOU HEARD US RIGHT. SHOVE<br>[09:15] IT UP YOUR ugly ass. Bring your<br>[09:16] workload. Bring your models. Bring your<br>[09:18] claw. We'll [ __ ] her. That's right.<br>[09:20] We'll [ __ ] your claude. Because with Big<br>[09:22] Jeff's Trainium Ultra Servers, you're<br>[09:24] [ __ ] 64 ways from Sunday. Take a hike<br>[09:26] to Big Jeff's Trainium Hell, HOME OF<br>[09:28] CHALLENGE TRAINING. THAT'S RIGHT,<br>[09:30] CHALLENGE TRAINING. How does it work? If<br>[09:32] you can train a trillion parameter model<br>[09:34] and not run to Nvidia, you get another<br>[09:35] round of funding. Don't wait. Don't<br>[09:37] delay. Don't [ __ ] with us or we'll rip<br>[09:39] your nuts off. Only at Big Jeff's<br>[09:41] Cranium Hell. The only cloud provider<br>[09:43] that tells YOU TO [ __ ] OFF. Hurry up,<br>[09:45] [ __ ] This event ends the minute we<br>[09:46] write you a check and you better not<br>[09:48] spend it anywhere else or you're a dead<br>[09:49] [ __ ] Go to hell. Big Jet<br>[09:51] Cranium Hell. Seattle's filthiest and<br>[09:53] exclusive home of the meanest sons of<br>[09:54] [ __ ] in the state of Washington.<br>[09:56] Guaranteed.<br>[09:57] >> Hopefully you now better understand why<br>[10:00] people don't want those GPUs as<br>[10:02] researchers. So, the researchers don't<br>[10:04] want the tranium GPUs. Crazy. It's such<br>[10:08] a a novel insight that I have there.<br>[10:10] There's no way I know this for sure. You<br>[10:12] get the idea. Researchers [ __ ] hate<br>[10:14] Tranium. They [ __ ] hate Google TPUs.<br>[10:15] They just want their Nvidia GPUs. They<br>[10:17] just want their CUDA. That's what<br>[10:18] they're here for. So, what does<br>[10:20] Enthropic do about that? Well, they've<br>[10:23] done a couple things to solve this<br>[10:25] problem. They did the much more<br>[10:27] aggressive limitations, which we've all<br>[10:28] seen and talked about. If you watch any<br>[10:30] of my videos, you've heard about that by<br>[10:31] now. Not going to harp on it. But the<br>[10:33] limiting of users and integrations was<br>[10:34] absolutely a play to restrict the usage<br>[10:37] of cloud code such that they had more<br>[10:40] GPUs available and more TPUs as well for<br>[10:43] whatever else they wanted to do. But the<br>[10:45] more important piece here, and I really<br>[10:46] want to emphasize this point, the<br>[10:48] massive price inflation. But Theo,<br>[10:51] between Opus 41 and Opus 45, they cut<br>[10:54] the price in a third. It used to be $75<br>[10:57] per mill out, and now it's only $25 per<br>[10:59] mill out. Yeah, nobody used Opus before,<br>[11:02] though. They pulled a fast one on us.<br>[11:04] Previously, they had three tiers. They<br>[11:06] had haiku, Sonnet, and Opus. The way<br>[11:10] that these tiers could be described<br>[11:11] really simply was that Haiku was for<br>[11:13] easy bulk stuff. Sonnet was for most<br>[11:17] real world stuff, especially coding, and<br>[11:20] Opus was an expensive research project<br>[11:22] that some people loved, but it was too<br>[11:24] expensive to be realistically usable.<br>[11:26] This was the tiering before, and they<br>[11:28] priced it accordingly. Cheap,<br>[11:30] reasonable, but still pretty pricey,<br>[11:32] absurdly ungodly [ __ ] expensive. But<br>[11:34] things have changed a bit because there<br>[11:36] is a fourth model here now, Mythos. And<br>[11:39] do you know what they did to us?<br>[11:43] That they just shifted the descriptions<br>[11:45] to the right. If we compare Opus 4 to<br>[11:47] Opus 45, yeah, sure, price went down,<br>[11:50] but that's not what happened. Opus45<br>[11:52] didn't replace Opus 41. Opus 45 replaced<br>[11:54] Sonnet. So, it's actually a price<br>[11:56] increase. They went from $15 per mill<br>[11:58] out to $25 per mill out for the model<br>[12:00] that the majority of us use the majority<br>[12:02] of the time. So, what's Haiku for now?<br>[12:04] It's for wasting money on wrong answers.<br>[12:06] I don't really know why else you would<br>[12:07] use it. There are many better, cheaper<br>[12:08] options that can work better in real<br>[12:11] world tasks. I I don't think Haiku is<br>[12:13] useful. Try out the mini models. Try<br>[12:15] some of the open weight models. A lot of<br>[12:17] them are good for the things I used to<br>[12:18] use Haiku for. They're also faster and<br>[12:19] way [ __ ] cheaper. Haiku is a deadline<br>[12:21] now. They they successfully tricked us<br>[12:23] all to bumping up a tier for everything.<br>[12:26] And this fancy tier at the end now is<br>[12:29] indeed an expensive research project<br>[12:30] that some people love. There's one<br>[12:32] additional line here, but you can't use<br>[12:33] it. Believe me, if Anthropic had the<br>[12:35] compute necessary to actually put Mythos<br>[12:37] out, probably would have by now. As much<br>[12:39] as I respect them for holding the line<br>[12:41] on the security thing, the line's been<br>[12:43] crossed by enough stuff now. It's it's<br>[12:44] time to release the [ __ ] model<br>[12:46] anthropic. Let's be real. But all of<br>[12:48] this is just part of the cost inflation.<br>[12:50] They got us to spend more per token by<br>[12:52] convincing us all to bump up to nicer<br>[12:54] models that cost more. But that's just<br>[12:57] part of the thing that they did here<br>[12:58] because the other issue is one of token<br>[13:01] outputs. We need to talk a bit about<br>[13:03] tokenization. Hopefully by now you've<br>[13:05] heard me talk about tokens and what they<br>[13:06] are. They're the chunks of text that we<br>[13:08] hand to the models that they then make<br>[13:09] their own chunks of text to put out.<br>[13:11] They're usually three to five<br>[13:12] characters. They're small sets of text<br>[13:14] that are how models generate responses.<br>[13:17] The number of tokens is what we are<br>[13:19] build on when we hit the APIs. The<br>[13:21] tokenizer for enthropic didn't change<br>[13:23] for a while from I believe sonnet 4 up<br>[13:25] till opus 46, but they changed it with<br>[13:27] 47. When it takes a piece of text and<br>[13:30] breaks it down, it breaks it down into<br>[13:32] more tokens. 30 to 50% more, which is an<br>[13:36] immediate 30% increase in your price,<br>[13:38] but it uses less tokens. Maybe if it<br>[13:41] gets the answer right quickly enough,<br>[13:42] but this is probably the scariest thing.<br>[13:45] Wrong answers cost more than right ones.<br>[13:47] If you tell the model, hey, go solve<br>[13:50] this problem. Even if it's a hard<br>[13:51] problem, if it solves it correctly, it<br>[13:53] knows it's correct. It verifies it's<br>[13:55] correct, and then it's done. If it can't<br>[13:57] solve the problem or it gets bad<br>[13:59] feedback, it will run in a loop forever.<br>[14:02] Correct answers can be as cheap as a few<br>[14:03] thousand tokens. Incorrect answers can<br>[14:05] be as expensive as a few million. And<br>[14:07] we're talking about 25 bucks per million<br>[14:09] tokens. We're talking bills as high as<br>[14:11] hundreds of dollars for an answer that<br>[14:13] isn't correct. And when we look at<br>[14:15] benchmarks like Deepsw SWE, the severity<br>[14:17] of this problem is obvious. GBT 5.4<br>[14:20] scored slightly better than Opus 47.<br>[14:22] Yes, I said 5.4, not 5.5, which scored<br>[14:25] way better. But if we compare 54 to Opus<br>[14:27] 47, remember Opus 47 is more expensive,<br>[14:30] 25 bucks per mill out versus 15 per mill<br>[14:32] out. So Opus more expensive by 80% or<br>[14:36] so, scored worse and generated 100,000<br>[14:39] tokens. By four, scored better and only<br>[14:41] did 67,000 tokens. By five, scored way<br>[14:44] better and only did 47,000 tokens. So<br>[14:47] again, with these realworld coding<br>[14:49] tasks, Opus models use twice as many<br>[14:52] tokens as equivalent OpenAI ones. Opus<br>[14:56] 4.6 did use way fewer tokens. Like from<br>[14:58] 46 to 47, they more than doubled the<br>[15:00] token usage, but it also scored like<br>[15:02] other [ __ ] in this bench. But this<br>[15:03] change in particular means that if you<br>[15:05] take the work you're already doing and<br>[15:09] switch from Opus 46 to 47, despite the<br>[15:12] fact that they are the same cost, you<br>[15:14] just doubled your spend. simply because<br>[15:17] you're using twice as many tokens. And<br>[15:19] you can see that in the score versus<br>[15:21] cost charts here where Opus46 cost $4.70<br>[15:25] per run and Opus 47 cost $16 per run. 55<br>[15:30] was only $5.80 and 54 was only $3.30 for<br>[15:33] better intelligence than any of the<br>[15:35] anthropic ones for these types of code<br>[15:37] tasks. That is almost certainly a big<br>[15:40] portion of their revenue growth. the<br>[15:42] fact that the cost to use their<br>[15:44] state-of-the-art tripled in the last few<br>[15:46] months after 10xing over the last year.<br>[15:49] Even if the number of customers did not<br>[15:52] go up week over week like it is right<br>[15:54] now, their revenue would still be going<br>[15:56] up as more people move to the better<br>[15:58] model, they end up spending way more.<br>[16:00] And also, let's be realistic. As people<br>[16:02] start to realize how powerful these<br>[16:04] models are, they start using them for<br>[16:05] more things. I know that my number of<br>[16:07] tokens per month consistently goes up.<br>[16:09] Even when things get more efficient, I<br>[16:11] just end up writing more code and<br>[16:12] generating more stuff. So, their<br>[16:14] customers are generating more tokens.<br>[16:15] They are using these models for more<br>[16:17] things and per task they're spending<br>[16:19] three times more. If you double the<br>[16:21] number of customers, you double their<br>[16:23] usage and then you triple their costs,<br>[16:26] you just 12xed your revenue. But the<br>[16:28] craziest thing is that my conspiracy is<br>[16:30] that they weren't actually trying to<br>[16:31] increase revenue with a lot of these<br>[16:33] changes. I think they were trying to<br>[16:35] save their GPUs. I think they increased<br>[16:38] the cost in hopes of people using the<br>[16:41] models less or using them for more<br>[16:42] efficient things to free up compute for<br>[16:45] their intended use cases for research.<br>[16:48] But they have learned the hard lesson<br>[16:50] quickly. When people like your models,<br>[16:52] they will keep using them more and they<br>[16:54] will pay basically whatever to do it.<br>[16:55] Especially when they're not the one<br>[16:56] footing the bill in the end. If you're<br>[16:58] an engineer at a company and you<br>[17:00] suddenly got to jump from using shitty<br>[17:01] C-pilot integrations to actually<br>[17:03] embracing Claude code and Opus, that is<br>[17:06] a 10x improvement. While I do prefer<br>[17:09] codec to cla code, I would say it's like<br>[17:11] 10% better. Claude Code to everything<br>[17:14] before it is like 10x better. So, if<br>[17:16] you're a company that was using Copilot<br>[17:19] or [ __ ] I don't know, Amazon's awful<br>[17:21] Nova models for things, you probably<br>[17:23] didn't think AI was that great. Then<br>[17:24] finally someone tries out opus during<br>[17:26] the holiday break on their cloud code<br>[17:28] locally. They realize it's insane. They<br>[17:30] come to work and say can we please<br>[17:31] please use this? The company says okay<br>[17:32] fine sure. Now suddenly people are<br>[17:35] experiencing good AI for the first time<br>[17:37] ever without even having to leave the<br>[17:39] cloud of choice. They all start spending<br>[17:41] way more on it. The costs go up not just<br>[17:43] because people are using it more but<br>[17:44] because the new model uses more tokens.<br>[17:46] Then you end up with that curve up and<br>[17:48] to the right. more customers spending<br>[17:50] more money doing more things with more<br>[17:51] models and of course more tokens. It<br>[17:54] makes all the sense in the world that<br>[17:55] their revenue has gone up so fast<br>[17:57] because even without the customer growth<br>[17:59] number goes up to the right. But we're<br>[18:00] only talking about half of the formula<br>[18:03] for profitability. We're just talking<br>[18:05] about the income. We got one other part<br>[18:07] to talk about here. Costs. In order to<br>[18:10] become profitable, your revenue has to<br>[18:12] grow faster than your costs grow.<br>[18:14] Anthropic costs have grown immensely as<br>[18:17] they keep doing all of these crazy<br>[18:18] compute allocations and hiring so many<br>[18:20] of the best people in the world. But<br>[18:22] their costs have a ceiling for how fast<br>[18:24] they can grow because they're limited on<br>[18:26] one particular issue, comput<br>[18:28] availability. It does not matter how<br>[18:31] much money anthropic wants to spend on<br>[18:33] compute if the compute doesn't exist. If<br>[18:35] all of Nvidia's manufacturing is bought<br>[18:37] out until 2028, it doesn't really matter<br>[18:40] how much money is willing to spend. They<br>[18:42] won't get those GPUs until 2029, unless<br>[18:45] they rent them from their competitors,<br>[18:47] which is what they've been doing, which<br>[18:49] can massively increase their spend, but<br>[18:52] not as much as committing to spend for<br>[18:55] future generations, which is what OpenAI<br>[18:57] and other companies have been doing.<br>[18:58] OpenAI incurred way more costs this year<br>[19:01] because they have all of these contracts<br>[19:03] they formed before to get as much<br>[19:05] compute as humanly possible. Anthropic<br>[19:08] was more conservative with their compute<br>[19:09] bets, which means that their spend did<br>[19:11] not ramp up quite as fast. But it also<br>[19:14] means they don't have enough compute to<br>[19:15] do the things they want to do right now.<br>[19:16] And that's why they're doing crazy<br>[19:18] things like partnering with XAI after<br>[19:20] banning them from using cloud models<br>[19:22] just months before. So while I do think<br>[19:24] Anthropic's profitability is somewhat<br>[19:27] accidental due to not spending enough on<br>[19:29] compute and raising prices a bunch to<br>[19:32] reserve the compute they had, the<br>[19:33] profitability is real. Which leads us to<br>[19:36] an important question. Is this product<br>[19:38] market fit? For those who aren't in the<br>[19:40] startup world, the concept of product<br>[19:42] market fit is the idea that your product<br>[19:44] has such high demand and has penetrated<br>[19:47] the market in such a way that it will<br>[19:49] continue to grow. You just have to kind<br>[19:51] of ride the wave at that point. This is<br>[19:53] the goal of all businesses. You want to<br>[19:55] have growth and demand that's so high<br>[19:58] that you are almost destined for success<br>[20:00] as long as you can keep putting out<br>[20:01] fires fast enough. It's a concept that<br>[20:03] came from Mark Andre and it's the<br>[20:05] alignment between the market and the<br>[20:06] product. Doesn't matter how good your<br>[20:08] product is if the market doesn't want<br>[20:10] it. Doesn't matter how good the market<br>[20:11] is if your product [ __ ] So the question<br>[20:13] is have they hit PMF now? Is are the<br>[20:16] major labs at a point now where the<br>[20:18] product and the market are properly<br>[20:20] aligned? Simon Willis seems to think so.<br>[20:22] We're not going to read this whole thing<br>[20:24] with the links in the description if<br>[20:25] you're interested in it yourself.<br>[20:26] Anthropic is strongly rumored to have<br>[20:28] their first profitable quarter. There<br>[20:29] are lots of stories circulating about<br>[20:31] companies surprised by how big their LLM<br>[20:33] bills have gotten and how often they're<br>[20:34] being used by their staff. I think this<br>[20:36] is because OpenAI and Enthropic have<br>[20:38] both found PMF. The first big piece is<br>[20:40] the pricing specifically that enterprise<br>[20:42] customers are now paying API prices.<br>[20:44] When you and I use things like Claude<br>[20:46] Code or Codeex, we are paying the $100<br>[20:49] or $200 tiers, but we're not getting<br>[20:51] $100 to $200 of API usage. So, with my<br>[20:54] personal usage of codecs, which I am<br>[20:56] paying the 200 bucks a month for right<br>[20:58] now, as a less heavy user than people on<br>[21:01] my team, I am still doing $553 of<br>[21:04] inference on that $200 plan. Other<br>[21:07] members of my team have gotten as high<br>[21:08] as like three plus,000<br>[21:11] for the 200 bucks. And as long as we're<br>[21:13] on those personal tiers, we can get what<br>[21:15] feels to be pretty close to unlimited<br>[21:17] usage. And that's the experience that<br>[21:19] Simon's had, too. For his $100 tier on<br>[21:22] Anthropic, he got $1,200 of tokens. And<br>[21:25] for his $100 tier on OpenAI, he got<br>[21:27] $1,000 of tokens. Simon had incorrectly<br>[21:29] assumed that companies making extensive<br>[21:31] use of agents were getting similar<br>[21:33] discounts. Turns out, I could not have<br>[21:34] been more wrong. He hasn't been able to<br>[21:36] track down the exact date, but at some<br>[21:38] point in the last 6 months, Anthropic<br>[21:39] switched their enterprise plan, which<br>[21:41] used to be seats including enough usage<br>[21:43] for a typical workday to now being $20<br>[21:46] per seat per month, plus API pricing for<br>[21:48] usage. Many customers are just finding<br>[21:50] out about this as they renew their<br>[21:51] contracts and their spend is going up<br>[21:54] massively. Openi did the same thing for<br>[21:56] their enterprise plans for CHBT business<br>[21:58] and enterprise in particular. A little<br>[22:00] harder to decode because they're quoting<br>[22:02] prices in credits, but as far as Simon<br>[22:04] can tell, these credit costs are an<br>[22:06] exact match for the API token cost<br>[22:08] listed. Yep. And they have been brutal<br>[22:10] about giving discounts. I've experienced<br>[22:12] this myself. Even committed spend as<br>[22:14] much as like 40k a month. You're lucky<br>[22:16] to get more than 5% off. And when you<br>[22:18] consider that the rumors for the profit<br>[22:20] margins for the hosting and metal costs<br>[22:23] relative to the API price are as much as<br>[22:26] 90% margins as in like you spend 10<br>[22:29] bucks for tokens, they profit $9 for<br>[22:31] those tokens. That means they could make<br>[22:34] better deals, but they're just not doing<br>[22:37] it. Simon also calls out that 55 is 2x<br>[22:40] the API cost of 54. It's also way more<br>[22:42] efficient, so that's not as simple a<br>[22:44] change as it looks, but Opus 47 is<br>[22:46] around 1.4x 4x the price of Opus 46 just<br>[22:48] from the tokenizer. But again, when it's<br>[22:51] doing so many more tokens, it ends up<br>[22:53] being closer to 3x costs in the real<br>[22:55] world. But the craziest thing isn't the<br>[22:57] cost increases, it's that companies are<br>[22:59] still paying them. They're not losing<br>[23:01] customers because the prices went up. In<br>[23:03] fact, companies are spending more and<br>[23:04] doing more with them. So why are they<br>[23:06] suddenly being so aggressive with<br>[23:08] pricing? It's because they're planning<br>[23:09] to IPO, sure, but it's also, according<br>[23:11] to Simon, because they probably found<br>[23:13] PMF finally. These coding agents are<br>[23:15] just so powerful that once you start<br>[23:17] using them, you're willing to pay absurd<br>[23:19] amounts of money to keep using them.<br>[23:21] Like, if you took away codecs from me<br>[23:23] and said I had to pay $2,000 to keep<br>[23:25] using it, I'd probably go back to Claude<br>[23:27] Code until they did the same thing,<br>[23:28] which they probably would have done<br>[23:29] first. I get it. I understand. If I had<br>[23:32] to pay the $2,000 to use these things<br>[23:34] the way I'm using, I would have to make<br>[23:36] some hard decisions. This is a huge<br>[23:38] contrast to the popularity of chatbt<br>[23:41] before where despite having 900 million<br>[23:43] people using chatbt every week, only 50<br>[23:45] million, which is 5% were actually<br>[23:47] paying money for it. And if OpenAI wants<br>[23:49] to spend a trillion dollars in infra,<br>[23:51] they'd have to have a billion customers<br>[23:53] for 4 years to make that much money. It<br>[23:55] just wouldn't work. But if companies are<br>[23:57] spending over $200 per month per user,<br>[23:59] you'll get there way, way faster. You<br>[24:02] can see this focus from OpenAI and<br>[24:03] Anthropic just by looking at their job<br>[24:05] listings. OpenAI has 703 open jobs.<br>[24:08] Roughly 30% are for enterprise sales.<br>[24:11] Anthropic has 390 and roughly 27% are<br>[24:14] for enterprise stuff. It's pleasingly<br>[24:15] ironic that these AI labs have picked a<br>[24:18] business model with such a heavy demand<br>[24:20] on human labor. Enterprise sales<br>[24:21] contracts don't close themselves without<br>[24:23] a whole lot of humans in the mix. It is<br>[24:25] always hilarious to me how much<br>[24:26] enterprise sales differs from like any<br>[24:28] other thing. Like I know people whose<br>[24:29] job is to like bring people to baseball<br>[24:32] games to try and get them to sign a<br>[24:33] crazy contract. It's a weird field, but<br>[24:35] even these labs have to play by those<br>[24:37] rules if they want to have these types<br>[24:39] of sales. This is also a big part of why<br>[24:40] OpenAI is breaking up with Microsoft<br>[24:42] because they really want their [ __ ]<br>[24:43] available in all the different clouds so<br>[24:45] they can do more enterprise selling. I<br>[24:47] like that Simon calls out these stories<br>[24:48] that are massively overblown. A lot of<br>[24:50] people have been asking me to cover the<br>[24:52] Microsoft cancellations of cloud code<br>[24:54] licenses. I didn't cover this because<br>[24:57] it's not true. Sure, they're not going<br>[24:59] to let employees use cloud code<br>[25:01] directly. That's because they are now<br>[25:02] routing through the GitHub co-pilot CLI,<br>[25:04] still using the same quad models, still<br>[25:06] paying Anthropic the same money as part<br>[25:08] of the new deal that they just shifting<br>[25:10] of where they are using the model, not a<br>[25:13] change in Microsoft's willingness to<br>[25:14] spend on anthropic models. It's just a<br>[25:16] dishonest thing to report on. And while<br>[25:19] the Uber case is more interesting where<br>[25:20] Uber blasted through their entire year<br>[25:23] AI spend budget in the first three<br>[25:25] months of the year, that's because they<br>[25:27] went from using models that were kind of<br>[25:29] useful for autocomplete sometimes to<br>[25:31] models that are able to do full end to<br>[25:33] end [ __ ] that are also more expensive at<br>[25:35] the end of last year and they didn't<br>[25:36] update their budgeting based on the<br>[25:38] existence of Opus 45 and other similarly<br>[25:40] competent models. I think this all comes<br>[25:43] down to the single biggest thing that<br>[25:45] resulted in the profitability of<br>[25:47] Anthropic. Opus 4.5. I cannot properly<br>[25:52] enough emphasize how much this changed<br>[25:54] everything, not just for Anthropic, but<br>[25:55] AI as a whole. As the OpenAI fanboy I'm<br>[25:58] often accused of being, they had nothing<br>[26:00] close at the time. Opus 45 was so good<br>[26:02] that it turned me into an anthropic<br>[26:04] fanboy for a bit. This model was a huge<br>[26:07] shift in how big of tasks we could trust<br>[26:10] the AI to go do. And it made me move<br>[26:12] away from using AI to edit a file for me<br>[26:15] to using AI to solve real complex<br>[26:17] problems. And a lot of this growth is<br>[26:20] the sentiment win that anthropic earned<br>[26:22] with Opus45 being so good. And OpenAI<br>[26:25] has to catch up. These companies take 3<br>[26:28] months to two years to understand what's<br>[26:30] going on. and enterprise is slow, but<br>[26:32] Obus45 ushered in a new era of AI<br>[26:35] capabilities and expectations. It took 3<br>[26:37] months or so to kick in for enterprises,<br>[26:39] but they're starting to spend based on<br>[26:41] this model's success. And I would<br>[26:43] imagine that OpenAI is not far behind<br>[26:45] just knowing how long these things take.<br>[26:47] So, in the end, Anthropic did earn their<br>[26:49] profit, even if a lot of that is cuz<br>[26:51] they didn't have enough spend allocated<br>[26:53] to compute. They are charging more. They<br>[26:55] do have more customers. Their customers<br>[26:57] are using their models for more things<br>[26:58] and they're using them on all of the<br>[26:59] different clouds. It is obvious to me<br>[27:01] why they're making so much money. It's<br>[27:03] because they made something incredible.<br>[27:04] They continued iterating well enough and<br>[27:07] then sold it hard enough to make a<br>[27:09] shitload of money. This was always going<br>[27:11] to happen, but I thought the turning<br>[27:12] point would be more next year at<br>[27:15] earliest. The fact that it happened now<br>[27:17] shows just how crazy these things are<br>[27:19] going and how much demand there is for<br>[27:21] inference right now. I think that's all<br>[27:23] I have to say on this topic. Congrats to<br>[27:25] Anthropic for the profit and congrats to<br>[27:27] all my friends who are there who are<br>[27:29] suddenly much more wealthy. Y'all earned<br>[27:31] it. As much as I love talking [ __ ]<br>[27:33] Anthropic put themselves where they are<br>[27:34] now. They earned this spot. But I am<br>[27:36] rooting for competitors to negotiate<br>[27:38] down prices because Anthropic is only<br>[27:40] able to charge this much because they<br>[27:42] don't really have competition until<br>[27:45] OpenAI models are in AWS. Kind of just<br>[27:47] ran around in circles like an Anthropic<br>[27:49] model does on a hard task. So, I'm going<br>[27:51] to end quickly like a Gemini model<br>[27:52] without much warning. Peace nerds.
<!-- deep-read:sections end -->
📄 **Full text:** ![[Full Document Contents/Articles/Holy Sht I Think Anthropic Is Profitable Now.md|Holy Sh*t I Think Anthropic Is Profitable Now by YouTube]]
## Highlights
- three letters, AWS. I am regularly surprised how many people don't understand the value of these three letters here because unlike OpenAI, anthropic models are hostable on AWS. In fact, they're the only reasonable model option you have on AWS. Obviously, if I have the choice between an anthropic model and an OpenAI model, I tend to lean OpenAI. But if my options are a bunch of crappy openweight models, some even worse Amazon Nova models, or Opus 47, you bet your ass I'm picking Opus. AWS is powering more than 90% of Fortune ([View Highlight](https://read.readwise.io/read/01ksq9errdrgs5kyaftd1zpd64))
- Note: Distribution moat: Anthropic is the only viable model on AWS (which powers 90%+ of Fortune 100). Even if you prefer OpenAI, Bedrock pushes you to Claude.
- Tags: enterprise-ai, multi-cloud, atom/literature/h1
- reasonable, but still pretty pricey, absurdly ungodly [ \_\_ ] expensive. But things have changed a bit because there is a fourth model here now, Mythos. And do you know what they did to us? That they just shifted the descriptions to the right. If we compare Opus 4 to Opus 45, yeah, sure, price went down, but that's not what happened. Opus45 didn't replace Opus 41. Opus 45 replaced Sonnet. So, it's actually a price increase. They went from $15 per mill out to $25 per mill out for the model ([View Highlight](https://read.readwise.io/read/01ksq9f0wfzcknemb5prw6e13q))
- Note: Pricing sleight-of-hand: "Opus 4.5 replaced Sonnet, not Opus 4.1" — the tier names slid right, so what looks like a price drop is actually $15→$25/M out.
- Tags: atom/literature/h2, pricing, tier-shift
- those tokens. That means they could make better deals, but they're just not doing it. Simon also calls out that 55 is 2x the API cost of 54. It's also way more efficient, so that's not as simple a change as it looks, but Opus 47 is around 1.4x 4x the price of Opus 46 just from the tokenizer. But again, when it's doing so many more tokens, it ends up being closer to 3x costs in the real world. But the craziest thing isn't the cost increases, it's that companies are still paying them. They're not losing
customers because the prices went up. In fact, companies are spending more and doing more with them. So why are they suddenly being so aggressive with pricing? It's because they're planning to IPO, sure, but it's also, according to Simon, because they probably found PMF finally. These coding agents are just so powerful that once you start using them, you're willing to pay absurd amounts of money to keep using them. Like, if you took away codecs from me and said I had to pay $2,000 to keep using it, I'd probably go back to Claude Code until they did the same thing, which they probably would have done first. I get it. I understand. If I had
to pay the $2,000 to use these things the way I'm using, I would have to make some hard decisions. This is a huge contrast to the popularity of chatbt before where despite having 900 million people using chatbt every week, only 50 million, which is 5% were actually paying money for it. And if OpenAI wants to spend a trillion dollars in infra, they'd have to have a billion customers for 4 years to make that much money. It just wouldn't work. But if companies are spending over $200 per month per user, you'll get there way, way faster. You ([View Highlight](https://read.readwise.io/read/01ksq9fsxmx7pe379nn56tm06v))
- Note: PMF-via-coding-agents thesis: prices rose dramatically AND companies are spending more (>$200/user/month). Unlike ChatGPT's 5% paying rate, enterprise coding tools have inelastic demand.
- Tags: atom/literature/h2, pmf, enterprise-spending