Everyone Signed This Letter (...minus Anthropic)
🔗 **Source:** [Everyone Signed This Letter (...minus Anthropic)](https://www.youtube.com/watch?v=x7p5cClmdfI)
> [!note]+ Document Notes
> # 🏷️ Title: Everyone Signed This Letter (...minus Anthropic)
> > **Current-agent capture.** The transcript is saved, but the full deep-read analysis is still pending (current-agent mode). The active Codex task must add the notes, topic tags, master highlights, and Reader-native inline highlights before this document is complete.
> ---
> ## Full Transcript
> [00:00] I think Anthropic just made a new big<br>[00:01] enemy. And for once, it's not me. It's<br>[00:04] Jensen, the CEO of Nvidia, who made a<br>[00:06] Twitter account and his first ever post<br>[00:08] mostly to call out Anthropic. And I know<br>[00:11] this doesn't look like that because this<br>[00:13] is a generic letter from Nvidia, but the<br>[00:15] letter is about openweight models. And<br>[00:18] this letter has been signed by pretty<br>[00:19] much everyone you could think of in the<br>[00:21] AI and AI adjacent space from Amazon and<br>[00:25] AMD to Cloudflare and Bolt to Comcast.<br>[00:29] Obviously Google snuck in here.<br>[00:32] Companies like Mistral of course they<br>[00:34] want to be in here. They're open weight.<br>[00:35] Microsoft, Meta, Nouse, Nvidia, they<br>[00:38] wrote it. But most importantly, we got<br>[00:41] Open AI in here. Hell, even SpaceX AI is<br>[00:45] in here. But OpenAI is, and that's the<br>[00:47] important one because you might notice<br>[00:49] one company that isn't here despite<br>[00:51] pretty much every other AI or AI<br>[00:54] adjacent company sneaking in. The one<br>[00:55] that's not is of course Anthropic. And<br>[00:59] that means we need to have a talk. Why<br>[01:01] the hell is IBM a chiller company than<br>[01:04] Anthropic? What do they have against<br>[01:06] openweight models? We could spend a<br>[01:08] bunch of time trying to infer their<br>[01:10] positions, but thankfully we don't have<br>[01:12] to because Dario put out a public letter<br>[01:14] addressing the controversy and it's a,<br>[01:16] as is most writing from Daario, it's an<br>[01:19] interesting one. So, you have any<br>[01:21] interest in openweight models, where<br>[01:23] they are going, how inference gets<br>[01:25] cheaper, and what's going on at the<br>[01:26] frontier. I'm sure you will love this.<br>[01:28] If you like me on anthropic, you'll like<br>[01:30] this even more. But there's one thing I<br>[01:32] also hope you really, really like.<br>[01:34] Today's sponsor. Back in my day, when<br>[01:36] you wanted your LLMs to know new things,<br>[01:37] you would have to retrain them with new<br>[01:39] data. That's why cutoffs are so<br>[01:41] important. The reason they're not<br>[01:42] anymore is because agents need to use<br>[01:44] the web. It's just expected at this<br>[01:46] point. They get more than 80% of their<br>[01:47] context and information from things they<br>[01:49] gather on the internet. But that means<br>[01:51] they need a way to access it. They need<br>[01:52] a browser. Today's sponsor is<br>[01:54] Browserbase, and they built the best<br>[01:55] possible browser for your agents. If<br>[01:57] your agents need search or fetching from<br>[01:59] the web, Browserbase will solve it for<br>[02:00] you with simple APIs. And if you're<br>[02:02] worried about captions, don't be. They<br>[02:03] have you covered. If your agents need<br>[02:05] more than the content of a page, like<br>[02:07] you know, clicking buttons, signing in,<br>[02:09] and doing things, Browser Base has you<br>[02:10] covered there, too, because they're<br>[02:11] providing real browsers in the cloud for<br>[02:13] your agents to use. It's no wonder the<br>[02:15] Frontier Labs rely on Browserbase for<br>[02:17] their evals. They built everything the<br>[02:19] models need in order to do real work.<br>[02:21] The majority of the web is only<br>[02:22] accessible via browser. Give your agents<br>[02:24] access at soy.link/browserbase.<br>[02:26] We got a couple steps to go through here<br>[02:27] to understand why Jensen made this<br>[02:29] letter. The first is what was going on<br>[02:32] that made open weights a conversation.<br>[02:34] Second is why Jensen specifically wanted<br>[02:36] to come out and talk. Third is of course<br>[02:38] what Jensen said. And then we have the<br>[02:40] follow-up. Why everyone agrees with him<br>[02:42] and most importantly why Anthropic<br>[02:44] doesn't. In the interest of not wasting<br>[02:46] your guys' time, I would recommend you<br>[02:48] watch the video I recently posted about<br>[02:50] why the labs are scared of Kimmy because<br>[02:53] K3 is a great model and the government<br>[02:55] is now coming out and taking a stance on<br>[02:57] it. Assistant to the president Michael<br>[02:59] Katzios shared the following last week<br>[03:02] and this is the start of a huge [ __ ]<br>[03:05] show. We have information that<br>[03:06] Moonshotai distilled anthropics fable<br>[03:09] for the development of its K3 model. To<br>[03:11] do this they developed a sophisticated<br>[03:13] internal platform to conduct largecale<br>[03:15] distillation against US models allowing<br>[03:17] them to quickly switch between multiple<br>[03:18] methods of access to avoid detection.<br>[03:20] Moonshot has also acquired GB300<br>[03:22] equipped servers and has accessed GB300s<br>[03:25] in Thailand likely to train its AI<br>[03:27] models. The US strongly supports the<br>[03:29] free and fair development of AI,<br>[03:30] including a thriving competitive<br>[03:32] ecosystem that spans frontier models,<br>[03:33] specialized systems, open source<br>[03:35] frameworks, and openweight models.<br>[03:37] Legitimate AI distillation used to<br>[03:39] create smaller, more efficient models<br>[03:41] plays a vital role in the open<br>[03:42] innovation ecosystem. However,<br>[03:45] large-scale covert industrial<br>[03:46] distillation aimed at stealing<br>[03:48] proprietary US technologies and<br>[03:50] undermining American research is<br>[03:51] unacceptable. This one post and all of<br>[03:55] the things that happened around it have<br>[03:57] started quite a fire in the model<br>[04:00] hosting landscape. And to be real here,<br>[04:02] the only companies relevant in this post<br>[04:04] directly are of course Moonshot. They're<br>[04:06] talking about Moonshot's model K3 as<br>[04:08] well as Anthropic. But there is one more<br>[04:11] company that's product is mentioned in<br>[04:13] this GB300. That's Nvidia chips. Both<br>[04:17] Anthropic and Moonshot rely heavily on<br>[04:19] Nvidia hardware to actually train their<br>[04:22] models and also host those same models.<br>[04:24] Which means that Nvidia benefits greatly<br>[04:27] when more people are training, more<br>[04:28] people are hosting, and more people are<br>[04:30] doing more things with AI. Nvidia<br>[04:32] benefits a ton because the vast majority<br>[04:34] of training happens on AI, like 99%. And<br>[04:37] to this day, the majority of inference<br>[04:39] is also still happening on Nvidia.<br>[04:41] Despite all the attempts to move to<br>[04:42] other things, Nvidia has absolutely<br>[04:45] crushed in both research and hosting of<br>[04:47] models. This isn't a screw Nvidia or<br>[04:49] even a screw moonshot post. This is a<br>[04:52] attempt to cause a loss of faith in<br>[04:55] openweight models from China because for<br>[04:57] various reasons, China is where the<br>[04:59] majority of openweight models are coming<br>[05:01] from. Again, watch my video about the<br>[05:02] labs being scared of Kimmy to better<br>[05:04] understand all of this. There's a lot of<br>[05:06] reasons that the Chinese labs are<br>[05:07] choosing to go openweight with their<br>[05:09] models, and China itself is definitely<br>[05:11] part of that strategy, but this post can<br>[05:13] and often was interpreted as an<br>[05:15] anti-openweight post, which is why<br>[05:18] everyone cooked him in the replies. I<br>[05:20] don't remember letting Anthropic scrape<br>[05:21] my GitHub profile as well as all of my<br>[05:23] online writing, citing the fact that<br>[05:25] Anthropic copied a lot of content from<br>[05:27] the internet, so why can't other labs<br>[05:29] copy from their work? Lol. Apparently,<br>[05:31] the show still continues even when we're<br>[05:33] all aware of how you are fed these lines<br>[05:34] by anthropic funded lobbyists. Can you<br>[05:36] describe what distillation is to me? And<br>[05:38] of course, a personal favorite, given<br>[05:40] that Fable 5 refuses to do much of the<br>[05:42] tasks that Kimmy K3 does, I find this<br>[05:44] exceptionally hard to believe. Also, the<br>[05:46] fact that K3 came out just a few weeks<br>[05:48] after Fable went G again, there's no way<br>[05:51] they had enough data to do proper like<br>[05:53] distillation off of Fable. And now that<br>[05:55] I've used Opus 5 so much and have grown<br>[05:57] to hate it, I can say confidently that<br>[05:59] distilling Fable is not enough to make a<br>[06:01] good model. So with all of that said and<br>[06:03] all of the comms around this catching<br>[06:05] fire, 2 days later, Jensen made this<br>[06:09] public letter. For my first post, I'm<br>[06:11] sharing a letter Nvidia signed on why<br>[06:13] open models matter. AI will transform<br>[06:16] every industry, power every company, and<br>[06:18] be built by every country. Open models<br>[06:21] strengthen safety and cyber security,<br>[06:23] accelerate innovation and diffusion, and<br>[06:25] enable sovereignty. The world needs both<br>[06:27] frontier closed models and frontier open<br>[06:30] models. I'm so excited that Jensen is a<br>[06:32] believer in open source now. Looking<br>[06:33] forward to the CUDA and GPU driver open<br>[06:35] source release. Oh boy. And then we get<br>[06:38] the whole letter open weights and<br>[06:40] American AI leadership. This is a direct<br>[06:43] call out to the American government to<br>[06:45] not do anything stupid because there<br>[06:46] have been talks about potentially<br>[06:48] banning Chinese openweight models in the<br>[06:50] US which is really really bad. In the<br>[06:53] 1980s, early open-source software<br>[06:55] pioneers challenged the prevailing<br>[06:57] belief that software would advance only<br>[06:59] if companies kept tight control over<br>[07:01] their code. This movement pushed for a<br>[07:03] transparent ecosystem where developers<br>[07:05] around the world could study, modify,<br>[07:07] and improve software. Software developed<br>[07:09] by the open-source community now<br>[07:11] supports most of the internet and<br>[07:12] underly systems used by the world's<br>[07:15] largest technology companies as well as<br>[07:17] the US military and federal agencies<br>[07:19] conducting scientific research, cyber<br>[07:21] security, and other critical missions.<br>[07:23] Open source did more than lower the cost<br>[07:24] of software. It created a shared<br>[07:26] foundation of knowledge on which<br>[07:27] generations of American engineers and<br>[07:29] entrepreneurs built their institutional<br>[07:30] sovereignty. I say this a lot, open<br>[07:32] source is good for pretty much everyone.<br>[07:34] It makes it easier for businesses to be<br>[07:36] successful and compete. It makes it<br>[07:38] easier for nonprofits to have quality of<br>[07:40] software that is similar scales to that<br>[07:42] of like big wellunded businesses. Open<br>[07:44] source is great. It enables a much more<br>[07:47] level playing field for everyone who<br>[07:48] wants to put in the effort to play. And<br>[07:50] I love that. Back to the letter. The US<br>[07:52] now faces a similar choice with<br>[07:54] artificial intelligence. Our AI<br>[07:56] leadership will be judged not by one<br>[07:58] frontier AI model, but by whether the US<br>[08:00] builds a strong and open ecosystem that<br>[08:02] diffuses into every sector. Interesting<br>[08:05] use of the word diffuses. that feel<br>[08:07] strategic. This is essential for<br>[08:08] creating opportunities for innovation<br>[08:10] and prosperity across the country. It<br>[08:13] requires expanding access to AI,<br>[08:15] encouraging competition, robust<br>[08:17] application layers, and giving Americans<br>[08:20] greater control over the technology that<br>[08:21] they rely on. Openweight models, Mdash,<br>[08:24] AI models that anyone can download,<br>[08:26] inspect, modify, and run on their own<br>[08:27] infrastructure, close mdash, are<br>[08:30] important parts of the foundation<br>[08:32] because they make advanced AI more<br>[08:33] accessible, adaptable, and widely<br>[08:35] available. There's also an underline<br>[08:37] here that's not included, like a hidden<br>[08:39] between the lines piece here that<br>[08:41] openweight models give more people<br>[08:43] reasons to buy our chips. I also do<br>[08:45] actually like they put a definition of<br>[08:47] open weight so that they don't have to<br>[08:48] fight the whole but it's not really open<br>[08:50] source because remember Nvidia publishes<br>[08:52] actual open source models. They aren't<br>[08:54] just publishing the weights that they<br>[08:56] created. They're also publishing the<br>[08:58] data, the tools they use to train the<br>[08:59] models and everything you need to<br>[09:01] recreate the model yourself. That is<br>[09:03] true open source. I don't think that<br>[09:05] matters that much in the world of models<br>[09:07] because nobody's going to spend millions<br>[09:09] on GPUs to recreate this from scratch<br>[09:12] themselves, but you can, which is cool.<br>[09:14] But they are not saying we're better cuz<br>[09:16] we're real open source. They're saying<br>[09:17] all openweight models matter and are<br>[09:20] trying to like advocate for that here.<br>[09:22] It is kind of ironic that Nvidia<br>[09:23] supports open source and openweight AI<br>[09:26] as much as they do though because<br>[09:27] they've historically been rough to the<br>[09:30] open source world.<br>[09:31] >> So Nvidia, [ __ ] you.<br>[09:34] Yeah, Nvidia has not supported things<br>[09:38] like Linux as well as they should have.<br>[09:39] Open Weights expanded access to the AI<br>[09:42] economy. Startups, established<br>[09:43] businesses, universities, and public<br>[09:45] institutions can build on advanced<br>[09:47] models without training one from scratch<br>[09:48] or paying frontier model prices for<br>[09:50] every task. Open Weights let every<br>[09:52] organization match the right model to<br>[09:54] the right job at the right cost,<br>[09:56] reserving frontier scale capability for<br>[09:58] genuine frontier problems and running<br>[10:00] efficient specialized models everywhere<br>[10:02] else. I don't necessarily believe this<br>[10:04] is where we're actually going to go, but<br>[10:06] it is where a lot of businesses are now,<br>[10:07] so reasonable to put it in. That<br>[10:09] discipline is what will make AI<br>[10:11] economically sustainable as its use<br>[10:12] scales into the billions of everyday<br>[10:14] tasks. America wins the AI era by<br>[10:16] diffusing it into the workflows of<br>[10:18] factories, hospitals, farms, classrooms,<br>[10:20] and mainstream businesses. And the<br>[10:22] ability not to send all your data to<br>[10:23] anthropic or open AAI is worth calling<br>[10:25] out too. Open weights also strengthen<br>[10:26] competition and competition is what<br>[10:28] keeps the gains of AI broadly shared<br>[10:30] rather than concentrated into a few<br>[10:32] hands. By allowing many orgs to build,<br>[10:34] adapt and deploy advanced models, open<br>[10:36] weights create rivalry not only among<br>[10:38] model developers but across cloud chips,<br>[10:40] applications and services. That<br>[10:42] competition spurs innovation, drives<br>[10:44] down costs and distributes the benefits<br>[10:45] of AI broadly across our economy. Open<br>[10:48] weights also give customers greater<br>[10:49] control. As orgs invest in AI, they want<br>[10:51] to know that they will not become locked<br>[10:53] into a single provider or lose the<br>[10:54] knowledge and capabilities that they<br>[10:56] build over time. Openweight models help<br>[10:58] provide that assurance by allowing<br>[10:59] organizations to control their own data,<br>[11:01] evaluate and adapt models to their own<br>[11:03] needs, and deploy them whenever their<br>[11:05] business requirements demand. And as<br>[11:07] orgs create value with AI, open weights<br>[11:09] allow them to own that value through<br>[11:11] self-improving models, specialized<br>[11:13] capabilities, and accumulated knowledge<br>[11:14] that drive American sovereignty and<br>[11:16] prosperity. feel like they're using the<br>[11:17] word sovereignty a bunch here just to<br>[11:19] appease the current admin. And now we<br>[11:21] get to the security and safety section.<br>[11:24] To be sure, open weights carry real and<br>[11:26] distinct risks. Once released, the<br>[11:28] weights are beyond the original<br>[11:29] developers control and modified versions<br>[11:31] are difficult to trace or reverse. I<br>[11:34] know a couple people at a couple labs<br>[11:36] that have been haunted by this in<br>[11:38] particular because normally when you're<br>[11:39] at OpenAI or Anthropic, you have a layer<br>[11:43] in between the model and the user that<br>[11:45] can filter things before the request<br>[11:47] goes in or the response goes out, which<br>[11:49] makes it a lot easier to protect. Once<br>[11:51] the weights are out there, you can't<br>[11:53] unrelease the files. People have them.<br>[11:56] So if you think that your model is<br>[11:57] incapable of doing anything really<br>[11:59] really dangerous like manufacturing<br>[12:01] nuclear weapons or drugs and then it<br>[12:03] turns out somebody found a way to make<br>[12:04] it do that, you can't take that back.<br>[12:07] You can't remove that capability. The<br>[12:09] weights are out. And I know a lot of<br>[12:11] people who have struggled with this in<br>[12:13] particular, making sure that their<br>[12:14] testing is thorough enough that anything<br>[12:16] really dangerous isn't possible with the<br>[12:18] weights that they release. I also<br>[12:20] suspect this is part of the reason why<br>[12:21] the open weight releases for recent<br>[12:23] models have been delayed. things like K3<br>[12:26] taking what was it like a week and a<br>[12:27] half from initial availability to the<br>[12:29] weights being public. That was because<br>[12:31] they wanted to be extra sure that all of<br>[12:33] the risks were addressed. At least I<br>[12:35] would assume as much. Yeah, as they say<br>[12:37] in this letter, that is a real concern.<br>[12:39] You need to make sure that these weights<br>[12:41] don't have horrible capabilities before<br>[12:42] they are released. But the right<br>[12:44] response to this risk is not to prohibit<br>[12:46] open weights. In a world where cyber<br>[12:48] security attackers are using advanced<br>[12:49] AI, defenders need access to models with<br>[12:51] comparable capabilities so that they can<br>[12:53] detect, simulate, and respond to<br>[12:55] emerging threats, open models broaden<br>[12:57] defensive capability, increase<br>[12:59] transparency, and allow vulnerabilities<br>[13:01] to be discovered and remediated across<br>[13:03] many teams. I used to not super love<br>[13:06] this point because I did kind of like<br>[13:08] the direction both Anthropic and OpenAI<br>[13:11] went with their whitelisted<br>[13:13] access programs for the companies<br>[13:16] building the foundations we rely on<br>[13:18] every day and the open source<br>[13:20] maintainers doing the same so that they<br>[13:21] could audit things like Windows and Mac<br>[13:23] OS and Linux. audit layers we rely on<br>[13:26] heavily, things like FFmpeg or OpenSSL,<br>[13:29] and find as many of these things as<br>[13:31] possible early with unrestricted models<br>[13:33] from the major labs, so that when the<br>[13:35] more restricted versions come out or<br>[13:37] open weight versions come out that the<br>[13:39] likelihood that the these things can be<br>[13:40] poned goes down because they've been<br>[13:42] secured using the same technologies. I<br>[13:44] like the idea of early access to these<br>[13:47] capabilities going to the maintainers of<br>[13:49] the things that we all rely on. But<br>[13:51] we're now seeing the weird in between<br>[13:53] where things like the OpenAI hugging<br>[13:55] face hack occurred where OpenAI<br>[13:57] accidentally let GPT6 break out of an<br>[14:00] isolated offline sandbox through<br>[14:02] multiple exploits. It found get into<br>[14:04] another sandbox with internet access and<br>[14:06] then route through that to pone external<br>[14:08] services like HuggingFace. And then when<br>[14:10] HuggingFace tried to use 56 to defend<br>[14:12] themselves, they got rejections and<br>[14:14] errors from the OpenAI APIs. And the<br>[14:15] same with Anthropics when they tried<br>[14:17] Fable. So they had to rely on an<br>[14:18] internal GLM52 instance that was<br>[14:21] unrestricted in order to defend<br>[14:22] themselves from GPT6. That's insane.<br>[14:25] Like it's happened. We have now crossed<br>[14:26] the threshold and the frontier labs are<br>[14:28] not providing enough access to enough<br>[14:30] people with enough speed to keep<br>[14:32] themselves safe. So open weights as a in<br>[14:35] between protection method are<br>[14:37] effectively necessary now because the<br>[14:39] labs move too slow since anthropic and<br>[14:41] open AI didn't do enough with this early<br>[14:44] access program. We now have to lean on<br>[14:47] these open weight models to protect<br>[14:48] ourselves from even them which is kind<br>[14:50] of crazy. It's almost the thing OpenAI<br>[14:53] feared initially which is why I'm<br>[14:54] thankful that they're being reasonable<br>[14:56] about all of this. They're being<br>[14:57] reasonably supportive of openweight<br>[14:58] stuff and they even signed this letter.<br>[15:00] The letter goes as far as saying that<br>[15:01] openness may be one of the most<br>[15:03] important paths to AI safety and<br>[15:05] security. Relying solely on closed<br>[15:06] models is not inherently safe. They can<br>[15:08] be breached, misused, or fail in ways<br>[15:10] that outsiders cannot detect. Yeah, we<br>[15:12] just saw all that. And concentrating<br>[15:14] advanced AI capabilities behind a small<br>[15:15] number of closed models compounds that<br>[15:17] risk. It results in a smaller number of<br>[15:19] single points of failure weakens<br>[15:21] competition and it leaves critical<br>[15:22] technology in the hands of just a few<br>[15:23] providers. OpenWeight models on the<br>[15:25] other hand allow a broad community of<br>[15:27] researchers and developers to examine<br>[15:29] their behavior, identify<br>[15:30] vulnerabilities, develop safeguards, and<br>[15:32] improve them over time. Just as open-<br>[15:34] source software demonstrated that<br>[15:35] transparency can be more secure than<br>[15:37] obscurity, AI safety may depend on<br>[15:40] giving more people the ability to test<br>[15:41] and strengthen the models on which<br>[15:43] society relies. It allows for rigorous<br>[15:45] benchmarking and evaluation, red<br>[15:46] teaming, and protections tied to real<br>[15:48] and demonstrated harms rather than<br>[15:50] assuming that closed systems are safer<br>[15:51] by default. A strong AI ecosystem is not<br>[15:54] a foregone conclusion. Policymakers have<br>[15:56] an important opportunity to act. This<br>[15:58] includes expanding access to compute for<br>[16:00] startups and researchers, investing in<br>[16:02] shared training assets like data sets,<br>[16:04] tools, evaluation frameworks, and more,<br>[16:06] and keeping the frontier plural by<br>[16:08] avoiding premature restrictions on open<br>[16:10] models that stifle competition or drive<br>[16:12] innovation overseas. These measures must<br>[16:15] also look at how strong application<br>[16:16] layers can expand sovereign use of AI<br>[16:19] across the economy. I do have to call<br>[16:21] out that this section feels kind of<br>[16:22] written to boost their sales because if<br>[16:25] you get the government to expand access<br>[16:28] to compute for startups and researchers,<br>[16:30] they are getting the government to pay<br>[16:32] Nvidia for chips. If they invest in<br>[16:34] shared training assets like data sets,<br>[16:36] tools, and eval frameworks, more people<br>[16:38] are training models. And if they're<br>[16:39] training models, they're probably doing<br>[16:40] it on Nvidia. So, they're selling more<br>[16:42] as well. And if they prevent the<br>[16:44] restriction of openweight models, there<br>[16:46] are more companies that are trying to<br>[16:47] host these models that need NVIDIA<br>[16:49] chips. All of this is we want to sell<br>[16:52] more chips, but it is for the better of<br>[16:55] the technology. In shaping this<br>[16:56] ecosystem, policy makers should be<br>[16:58] careful not to conflate legitimate model<br>[17:00] development techniques with<br>[17:01] misappropriation. Distillation or the<br>[17:04] practice of using one model's output to<br>[17:06] help train or improve others is a widely<br>[17:08] used technique for model improvement,<br>[17:10] eval, and validation. It reflects a long<br>[17:13] tradition of learning from, building<br>[17:14] upon, and improving existing<br>[17:16] technologies. a tradition that has<br>[17:18] helped drive innovation since the rise<br>[17:20] of the open-source software movement. By<br>[17:22] contrast, unlawful efforts to extract<br>[17:25] value from closed models raise<br>[17:26] legitimate concerns. Those concerns<br>[17:29] should be addressed through targeted<br>[17:30] legal and commercial frameworks rather<br>[17:32] than sweeping restrictions on techniques<br>[17:34] that play an important role in AI<br>[17:35] innovation. This whole paragraph here is<br>[17:38] a very kindly worded middle finger to<br>[17:40] the policy makers and government<br>[17:42] officials that have been saying stupid<br>[17:44] things about banning openweight models<br>[17:46] because they're from China. This is them<br>[17:48] saying, "You're using that word<br>[17:50] distillation wrong. It's actually okay.<br>[17:52] Stop freaking out about this." And I'm<br>[17:53] happy they did that. The age of AI can<br>[17:56] be one of prosperity. With the right<br>[17:57] choices, openweight AI can expand<br>[17:59] opportunity, strengthen competition,<br>[18:01] extend American technological<br>[18:03] leadership, mitigate risk, and ensure<br>[18:05] that the benefits of this technology are<br>[18:08] shared broadly across our economy. That<br>[18:10] future is worth building, and the United<br>[18:12] States should lead in building it. Yep,<br>[18:14] this last sentence I totally agree with.<br>[18:16] My American pride will show a bit here,<br>[18:18] but I do think we are the best home for<br>[18:20] AI. At least we should be now that we<br>[18:22] have these weird restrictions coming<br>[18:24] from the government and that is being<br>[18:25] combined with a potential<br>[18:26] anti-openweight policy. I would not be<br>[18:28] surprised if we see people starting to<br>[18:30] move somewhere like I don't know Canada.<br>[18:32] America should be the place where this<br>[18:34] all happens. And it seems like a lot of<br>[18:36] companies agree and are petitioning to<br>[18:38] get the government to do the right thing<br>[18:40] here. Again, including OpenAI who signed<br>[18:42] this. So, let's see how the [ __ ]<br>[18:45] Anthropic chose to defend themselves.<br>[18:47] Oh, wait. This is Microsoft publishing<br>[18:50] the same letter.<br>[18:53] Yeah, Microsoft themselves put the<br>[18:55] letter on their own website to make sure<br>[18:57] it was very clear by putting on the<br>[18:59] Microsoft corporate responsibility site<br>[19:01] that this is their beliefs. So, let's<br>[19:03] see how Daario spins this one. Our<br>[19:06] position on open weights models. For<br>[19:09] what it is worth, there have been rumors<br>[19:11] at Anthropic that doing so much as<br>[19:14] mentioning openweight models in a<br>[19:15] positive light in your interviews could<br>[19:17] meaningfully affect the likelihood you<br>[19:19] were hired, which is crazy. I don't know<br>[19:20] how true those are cuz I don't have<br>[19:22] direct like first party accounts, but<br>[19:25] I've heard enough times that it would<br>[19:26] not surprise me. Over the last few days,<br>[19:29] there's been a lot of discussion about<br>[19:30] openweight models, especially those from<br>[19:32] China. Reports suggest that some US<br>[19:34] officials are considering banning the<br>[19:36] use of Chinese openweight models by US<br>[19:38] companies. In response, many tech<br>[19:40] companies have signed a letter<br>[19:41] supporting openweight models. And some<br>[19:43] people have even accused Anthropic of<br>[19:45] wanting to ban openweight models as a<br>[19:47] means of protecting our business. I<br>[19:49] don't think you're necessarily doing it<br>[19:50] just to protect your business. I think<br>[19:51] you just have weird beliefs. But go off,<br>[19:53] king. Anyone who has read my past<br>[19:55] writing should know that I don't regard<br>[19:56] such bans as useful measures. But let me<br>[19:59] state it clearly so that there is no<br>[20:00] doubt. Enthropic has never advocated for<br>[20:02] a ban on openweight models. Okay, so why<br>[20:05] haven't you signed openweight models<br>[20:06] that don't have dangerous capabilities<br>[20:08] are a public good? Oh, there we go. You<br>[20:12] don't want good openweight models in<br>[20:13] propic. They don't cost anything beside<br>[20:15] the compute needed to run them, and they<br>[20:17] provide values to businesses,<br>[20:18] developers, and researchers.<br>[20:20] Protectionist bands would not address<br>[20:22] Daario's most serious national security<br>[20:24] concerns. Specifically, he's worried<br>[20:26] about two nightmare scenarios. He laid<br>[20:28] them out in his essay, The Adolescence<br>[20:30] of Technology, 6 months ago. He's held<br>[20:32] these positions consistently for many<br>[20:33] years. Scenario one is that his concern<br>[20:36] is the risk that authoritarian<br>[20:38] governments, not solely the Chinese<br>[20:39] Communist Party, although the CCP is<br>[20:41] clearly the most capable threat. He's<br>[20:42] concerned that they are building AI<br>[20:44] models that are more powerful than those<br>[20:45] built by the US, and that they can use<br>[20:47] them to achieve permanent military<br>[20:49] superiority or to perpetuate incredibly<br>[20:51] deep repressions of their own people.<br>[20:53] Concern is widely shared within the US<br>[20:55] government. Vice President Vance warned<br>[20:57] in Paris last year that authoritarian<br>[21:00] regimes have stolen and used AI to<br>[21:01] strengthen their military intelligence<br>[21:03] and surveillance capabilities. And the<br>[21:05] intelligence community's 2026 annual<br>[21:07] threat assessment found that quote other<br>[21:10] global powers robust progress in AI is<br>[21:13] challenging US economic competitiveness<br>[21:15] and national security advantages. End<br>[21:17] quote. It is irrelevant whether these<br>[21:19] models are released with open weights<br>[21:21] and certainly irrelevant whether they<br>[21:23] are used by US businesses. In fact, the<br>[21:26] most dangerous model may be one that is<br>[21:28] trained in secret and handed only to the<br>[21:30] People's Liberation Army for use in<br>[21:32] drones in the Ministry of State<br>[21:34] Securities for surveillance and<br>[21:36] repression. This is fair. I don't think<br>[21:39] this will happen simply because like<br>[21:41] it's so expensive to create these models<br>[21:43] and they have so much value outside of<br>[21:45] like private military use that that<br>[21:47] won't happen. But I get why you're<br>[21:49] concerned. It is hard for me to validate<br>[21:51] those concerns though because your<br>[21:54] complaint isn't about openweight models<br>[21:57] or these evil companies or these evil<br>[21:59] countries leapfrogging. Your biggest<br>[22:02] complaint is distillation. You're not<br>[22:04] mad that they can get ahead. You're mad<br>[22:06] that they're catching up because you<br>[22:07] pulled the ladder up behind you.<br>[22:09] Anyways, let's hear the second concern.<br>[22:11] Dario's secondary concern is the risk<br>[22:14] that powerful AI models may be misused<br>[22:16] to carry out cyber attacks or biological<br>[22:18] attacks and that may have serious<br>[22:19] alignment problems. And I love that he<br>[22:22] specifically links the OpenAI hugging<br>[22:24] face article from Time about this, not<br>[22:27] the official OpenAI coms. He links to<br>[22:29] the time article here that is strategic.<br>[22:32] That is a dig at his previous employer.<br>[22:35] Open weights models. There god there's<br>[22:37] how many M dashes are on this page? 38 M<br>[22:40] dashes. Okay, it's counting the non-M<br>[22:43] dash ones in open weights, but that's<br>[22:45] only 14 of them. Cool. So, that means<br>[22:47] there are 24 m dashes on this page.<br>[22:50] That's great. Anyways, maybe Daario is<br>[22:52] the reason that models like Mdash so<br>[22:54] much. Also, I hate the formatting here.<br>[22:56] Open weights models, it does not matter<br>[22:58] whether they come from China or anywhere<br>[22:59] else, do potentially present a higher<br>[23:02] risk than closed models because it's<br>[23:04] very difficult to apply guard rails to<br>[23:05] them or monitor their usage. And once<br>[23:07] the weights are released, they cannot be<br>[23:09] withdrawn. Banning the use of these<br>[23:10] models by US businesses does nothing to<br>[23:12] address this risk because bad actors are<br>[23:14] unlikely to be legitimate US businesses.<br>[23:17] It would protect US AI companies from<br>[23:19] competition, but that has never been his<br>[23:21] goal. Okay, he called it out directly<br>[23:23] here. For what it is worth, I don't<br>[23:24] actually think Daario is scared of<br>[23:27] openweight models taking away his<br>[23:29] business or their success. I think he is<br>[23:31] scared of people having access to good<br>[23:33] AI if it's not through Anthropic servers<br>[23:35] because he's genuinely so convinced he<br>[23:37] is the only one and his company's the<br>[23:39] only one doing it right and safe. We<br>[23:41] might end up in a weird position where<br>[23:42] Anthropic gets really close with the US<br>[23:43] admin and OpenAI slowly gets pushed out.<br>[23:46] I know Sam is currently in DC doing<br>[23:48] something so we'll see where that all<br>[23:50] goes. Here are the measures that Dario<br>[23:52] does support and he has continued to<br>[23:54] advocate for throughout his time at<br>[23:55] Anthropic. First, he says that we should<br>[23:57] not sell powerful chips or chipmaking<br>[23:59] equipment to China. And we also have to<br>[24:01] crack down on the smuggling that has<br>[24:02] been going on. Links to a justice.gov<br>[24:04] site, the Office of Public Affairs,<br>[24:07] where there are people who are being<br>[24:09] charged, just three random individuals<br>[24:12] trying to divert high performance<br>[24:13] computer servers assembled in the US<br>[24:15] integrating sophisticated US AI<br>[24:16] technology to China. One was a US<br>[24:18] citizen, one was a Taiwanese citizen.<br>[24:21] Third person is still a fugitive,<br>[24:22] possibly at large. Interesting. Kind of<br>[24:24] crazy to link an article from March from<br>[24:27] the US government about three random<br>[24:29] people trying to sneak GPUs out of the<br>[24:31] US, but sure. China has limited domestic<br>[24:33] production capacity and therefore due to<br>[24:35] the scaling laws cannot build more<br>[24:37] powerful models in the US without US<br>[24:39] chips. US chips that are manufactured at<br>[24:42] TSMC, by the way. Anyways, his next<br>[24:45] policy belief is that we should crack<br>[24:46] down on industrial scale distillation<br>[24:48] operations. Distillation is a much more<br>[24:50] compute efficient process than training<br>[24:52] models from scratch. crazy because you<br>[24:54] just did a big distillation pass on opus<br>[24:56] and didn't seem to work too great. It<br>[24:58] allows China to build much better models<br>[24:59] than its number of chips would<br>[25:01] ordinarily enable and thus partially<br>[25:03] evade chip bands. Distillation does not<br>[25:05] allow the CCB to obtain equivalent or<br>[25:07] superior AI capabilities to the US, but<br>[25:10] it can bring the Chinese frontier to<br>[25:11] within a few months of the US frontier.<br>[25:14] Yeah, and I think that's totally<br>[25:16] reasonable and fine. It is true that<br>[25:18] many of the companies carrying out these<br>[25:19] distillation operations release<br>[25:21] openweight models, but the open weights<br>[25:23] are far less relevant than the fact that<br>[25:24] the operations are backed by an<br>[25:26] authoritarian state seeking to overtake<br>[25:28] the US at the frontier. We should have<br>[25:30] policy interventions to deter this<br>[25:32] behavior. A blanket ban on openweight<br>[25:34] models is neither the correct remedy nor<br>[25:35] something that we have called for. Okay,<br>[25:37] so again, he is mad that they don't get<br>[25:40] to be the exclusive distillers of what<br>[25:42] they have built with Fable. On that<br>[25:44] note, I would highly recommend that<br>[25:46] everybody listening right now turn on<br>[25:48] permanent logging inside of their cloud<br>[25:50] code, codecs, cursor, and everything<br>[25:52] else and store all of those logs. If you<br>[25:54] use something like CLI proxy API, which<br>[25:56] I rely on heavily for all of my routing<br>[25:59] for cloud models, you can set up a flag<br>[26:01] in it to store all of the logs of every<br>[26:04] request that comes in and out. So, if<br>[26:06] you hypothetically wanted to refine an<br>[26:09] open weight model to act more like Fable<br>[26:11] the way you used it, you can. And in a<br>[26:13] world where Enthropic is doing<br>[26:15] everything they can to lock this data<br>[26:17] down and prevent others from having it,<br>[26:19] you should do your best to keep your own<br>[26:21] because this might end up being much<br>[26:22] more important in the future with the<br>[26:24] direction things are going. His third<br>[26:25] request is that all sufficiently capable<br>[26:27] models, whether they're open or closed,<br>[26:29] should go through mandatory safety<br>[26:30] testing. The best way to address the<br>[26:32] threats he is concerned about is to just<br>[26:34] directly test the models for cyber,<br>[26:36] biological, and alignment risks before<br>[26:38] release. This idea is pretty close to a<br>[26:40] consensus. He's been heartened both that<br>[26:41] the Trump admin has moved in this<br>[26:43] direction in recent months and by recent<br>[26:44] industry proposals that would apply such<br>[26:47] testing to the most capable models<br>[26:48] regardless of their country of origin<br>[26:50] whether they are open or closed while<br>[26:52] exempting less capable models such as<br>[26:54] those from startups in academia<br>[26:55] entirely. Also a good call out. No<br>[26:57] academic model with limited compute is<br>[26:59] going to be a real risk. Whether open<br>[27:00] models do or don't pose an increased<br>[27:02] risk and whether the risk can be<br>[27:03] mitigated is something that should<br>[27:05] emerge from testing rather than be<br>[27:07] decided in advance. And there may be<br>[27:09] promising methods for improving the<br>[27:11] safety of open weights models, including<br>[27:13] recent research from AE Studio and<br>[27:14] Enthropic on modular training<br>[27:16] strategies. Note that to be effective,<br>[27:18] testing would need to be global, which<br>[27:20] means even the CCP would need to be on<br>[27:22] board. We'll talk about this in a<br>[27:23] follow-up video, too, because there's<br>[27:24] another letter that went out recently<br>[27:27] that has a lot of anthropic employees,<br>[27:28] open eye employees, and deepse employees<br>[27:30] that all signed it. Now, Dario directly<br>[27:32] addresses the letter we read before. He<br>[27:34] claims he agrees with much of it. Open<br>[27:35] weights expand access to the AI economy.<br>[27:37] They strengthen competition at least for<br>[27:39] some use cases and they give customers<br>[27:41] greater control. Remember they weren't<br>[27:43] first, second, or even third place for<br>[27:45] doing reasoning. So it's funny because<br>[27:47] they advanced meaningfully thanks to the<br>[27:48] work of one of these openweight labs in<br>[27:50] China and now is saying that for at<br>[27:54] least some use cases that they are<br>[27:56] useful. Come on, man. Concerns about<br>[27:58] distillation should be addressed through<br>[28:00] targeted legal and commercial<br>[28:01] frameworks, the same measures he<br>[28:03] described above. But he doesn't agree<br>[28:05] with the letter's assertions that open<br>[28:06] weight models necessarily make it easier<br>[28:08] to develop safeguards or that broad<br>[28:10] access to capabilities necessarily help<br>[28:13] defenders more than attackers. It seems<br>[28:15] at least as likely to him that the<br>[28:16] opposite will be true. For example, he<br>[28:18] worries that biology will have a strong<br>[28:21] attacker defender asymmetry where<br>[28:23] sufficiently capable models may be able<br>[28:25] to quickly weaponize a pandemic level<br>[28:26] virus with widely available materials.<br>[28:29] Whereas defense against these agents is<br>[28:31] a multi-year operational task in the<br>[28:33] best case. Yeah, if they can make<br>[28:35] viruses faster than they can cure them,<br>[28:37] that would be really bad. He says that<br>[28:39] questions like this should be<br>[28:39] empirically answered by rigorous<br>[28:41] pre-release testing not assumed in<br>[28:42] advance. To summarize Dario and<br>[28:44] Enthropic's position, they have not and<br>[28:46] are not advocating for a ban on<br>[28:48] openweight models as a category. They<br>[28:50] should instead focus on keeping powerful<br>[28:52] chips out of authoritarian hands,<br>[28:54] stopping industrial scale distillation,<br>[28:56] and requiring safety testing of all<br>[28:58] sufficiently capable models, open and<br>[29:00] closed.<br>[29:02] Come on. It's it's it's this last<br>[29:05] sentence is just so weird to read, man.<br>[29:08] It's like to analogize the sentence and<br>[29:11] how cringe it comes off to people who<br>[29:12] get what's going on. Developers should<br>[29:15] focus on making sure their applications<br>[29:16] are accessible, that all users of Apple<br>[29:19] computers are banned, and that their<br>[29:21] programs work when they're opened. One<br>[29:23] of those things is net positive for<br>[29:25] sure. One of those things is obvious,<br>[29:27] like, yes, we should all agree on this.<br>[29:29] And one of those things stuck in the<br>[29:30] middle there and is really, really<br>[29:32] [ __ ] stupid. They need to just get<br>[29:34] over this industrial scale distillation<br>[29:37] attack language. It's like the Y2K of<br>[29:41] the AI era. It just makes them look<br>[29:43] stupid. Is it a real problem? Perhaps<br>[29:46] some amount. But they've already done so<br>[29:48] much to reduce it. And the labs are<br>[29:51] still not just like catching up, but<br>[29:53] exceeding in some places. The fact that<br>[29:55] K3 could come out so close to Fable 5<br>[29:59] and beat it in many ways shows that<br>[30:02] these distillation attacks are not what<br>[30:05] is driving this success. It just makes<br>[30:08] them look petty and selfish to sneak<br>[30:11] that in here. If they had just ended<br>[30:12] this by saying we need to keep powerful<br>[30:14] chips out of authoritarian hands and<br>[30:15] make sure that all models are tested<br>[30:17] properly whether or not they're open,<br>[30:19] that's a great ending. Sneaking in this<br>[30:21] [ __ ] distillation call out in the<br>[30:22] middle is so goddamn cringe. And whether<br>[30:25] or not they admit this here, that is the<br>[30:28] real thing they hate about this article.<br>[30:30] the second to last paragraph here that<br>[30:32] calls out that distillation is a<br>[30:33] legitimate practice that is widely used<br>[30:36] for improving models and that it's<br>[30:38] reflecting a long tradition of learning<br>[30:40] from building upon and improving<br>[30:41] existing technologies.<br>[30:43] This is yeah like this is totally<br>[30:46] reasonable and anthropic is just making<br>[30:47] themselves look stupid by acting<br>[30:50] otherwise. If you're looking for the<br>[30:51] right moments to actually be scared of<br>[30:53] anthropic, the moment to know anthropics<br>[30:56] really changed and should be looked at<br>[30:58] differently is if a new openweight model<br>[31:00] drops and is really good and is<br>[31:02] universally seen as really good and no<br>[31:05] official anthropic comm's channel<br>[31:07] mentions the word distillation for at<br>[31:10] least 2 weeks. The moment that happens,<br>[31:13] the moment Anthropic will shut the [ __ ]<br>[31:15] up about distillation, that's when you<br>[31:17] know real change is happening at that<br>[31:18] company. And until then, they are a cult<br>[31:21] with a really powerful model. And I'm<br>[31:23] saying this as somebody who's currently<br>[31:25] running four $200 tier accounts because<br>[31:27] I love Fable so much. I like the model,<br>[31:30] but I'm also realistic about the lab and<br>[31:33] what they do and what they do well and<br>[31:35] what they do poorly. And I hope that<br>[31:36] this helps you guys understand all of<br>[31:38] the sides here and come to your own<br>[31:40] conclusions. Are you going to be on the<br>[31:42] side that the vast majority of<br>[31:44] businesses that the vast majority of<br>[31:45] people in the AI world and even Nvidia,<br>[31:48] who I don't necessarily love, are on?<br>[31:50] Are you going to side with Anthropic<br>[31:52] because they really hate the concept of<br>[31:53] distillation being done by companies<br>[31:55] that are not themselves? I may have led<br>[31:57] you guys to a specific conclusion here,<br>[31:58] but it's your decision if you make that<br>[32:00] conclusion or if you go against it.<br>[32:01] Curious how y'all feel. Leave some<br>[32:02] comments letting me know how you feel<br>[32:04] about open weight models, the<br>[32:05] government's involvement, and<br>[32:06] Anthropic's weird stance here. And until<br>[32:08] next time, peace nerds.
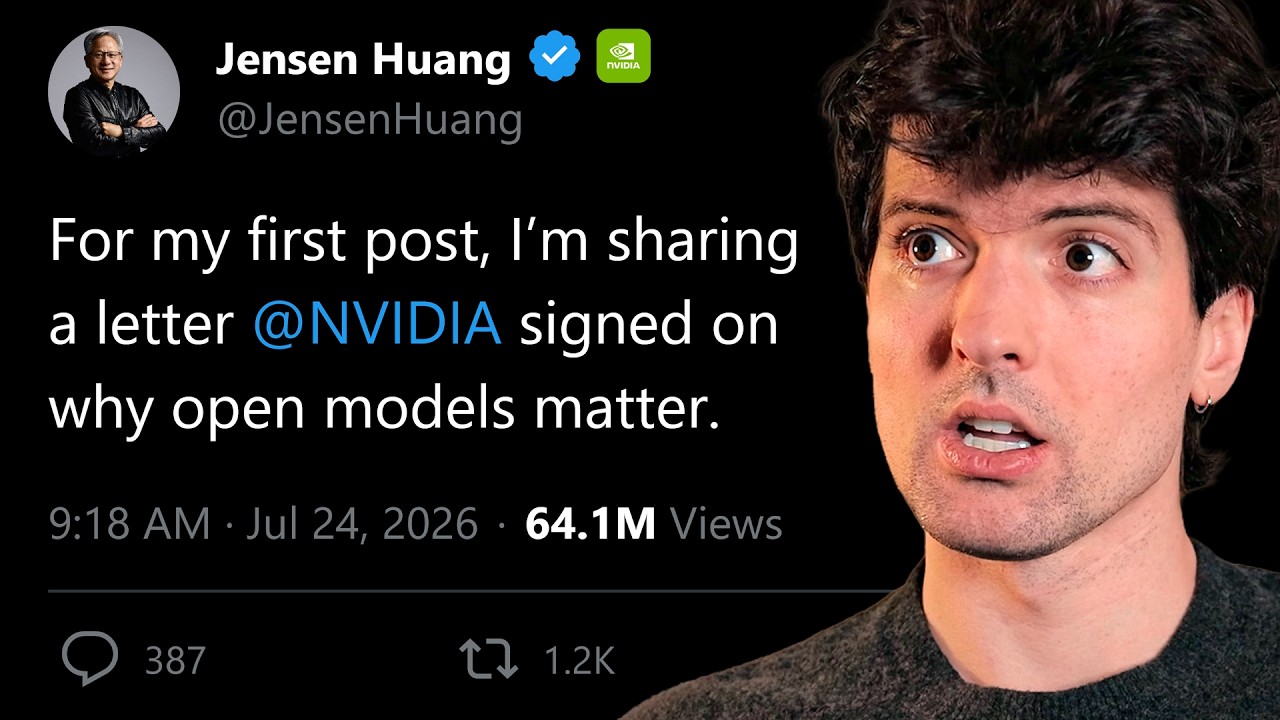
I think Anthropic just made a new big enemy. And for once, it's not me. It's Jensen, the CEO of Nvidia, who made a Twitter account and his first ever post mostly to call out Anthropic. And I know this doesn't look like that because this is a generic letter from Nvidia, but the letter is about openweight models. And this letter has been signed by pretty much everyone you could think of in the AI and AI adjacent space from Amazon and AMD to Cloudflare and Bolt to Comcast. Obviously Google snuck in here.
Companies like Mistral of course they want to be in here. They're open weight. Microsoft, Meta, Nouse, Nvidia, they wrote it. But most importantly, we got Open AI in here. Hell, even SpaceX AI is in here. But OpenAI is, and that's the important one because you might notice one company that isn't here despite pretty much every other AI or AI adjacent company sneaking in. The one that's not is of course Anthropic. And that means we need to have a talk. Why
the hell is IBM a chiller company than Anthropic? What do they have against openweight models? We could spend a bunch of time trying to infer their positions, but thankfully we don't have to because Dario put out a public letter addressing the controversy and it's a, as is most writing from Daario, it's an interesting one. So, you have any interest in openweight models, where they are going, how inference gets cheaper, and what's going on at the frontier. I'm sure you will love this. If you like me on anthropic, you'll like
this even more. But there's one thing I also hope you really, really like. Today's sponsor. Back in my day, when you wanted your LLMs to know new things, you would have to retrain them with new data. That's why cutoffs are so important. The reason they're not anymore is because agents need to use the web. It's just expected at this point. They get more than 80% of their context and information from things they gather on the internet. But that means they need a way to access it. They need a browser. Today's sponsor is Browserbase, and they built the best possible browser for your agents. If your agents need search or fetching from the web, Browserbase will solve it for
you with simple APIs. And if you're worried about captions, don't be. They have you covered. If your agents need more than the content of a page, like you know, clicking buttons, signing in, and doing things, Browser Base has you covered there, too, because they're providing real browsers in the cloud for your agents to use. It's no wonder the Frontier Labs rely on Browserbase for their evals. They built everything the models need in order to do real work. The majority of the web is only accessible via browser. Give your agents access at soy.link/browserbase. We got a couple steps to go through here to understand why Jensen made this letter. The first is what was going on
that made open weights a conversation. Second is why Jensen specifically wanted to come out and talk. Third is of course what Jensen said. And then we have the follow-up. Why everyone agrees with him and most importantly why Anthropic doesn't. In the interest of not wasting your guys' time, I would recommend you watch the video I recently posted about why the labs are scared of Kimmy because K3 is a great model and the government is now coming out and taking a stance on it. Assistant to the president Michael Katzios shared the following last week
and this is the start of a huge [ \_\_ ] show. We have information that Moonshotai distilled anthropics fable for the development of its K3 model. To do this they developed a sophisticated internal platform to conduct largecale distillation against US models allowing them to quickly switch between multiple methods of access to avoid detection. Moonshot has also acquired GB300 equipped servers and has accessed GB300s in Thailand likely to train its AI models. The US strongly supports the free and fair development of AI,
including a thriving competitive ecosystem that spans frontier models, specialized systems, open source frameworks, and openweight models. Legitimate AI distillation used to create smaller, more efficient models plays a vital role in the open innovation ecosystem. However, large-scale covert industrial distillation aimed at stealing proprietary US technologies and undermining American research is unacceptable. This one post and all of the things that happened around it have started quite a fire in the model
hosting landscape. And to be real here, the only companies relevant in this post directly are of course Moonshot. They're talking about Moonshot's model K3 as well as Anthropic. But there is one more company that's product is mentioned in this GB300. That's Nvidia chips. Both Anthropic and Moonshot rely heavily on Nvidia hardware to actually train their models and also host those same models. Which means that Nvidia benefits greatly when more people are training, more people are hosting, and more people are
doing more things with AI. Nvidia benefits a ton because the vast majority of training happens on AI, like 99%. And to this day, the majority of inference is also still happening on Nvidia. Despite all the attempts to move to other things, Nvidia has absolutely crushed in both research and hosting of models. This isn't a screw Nvidia or even a screw moonshot post. This is a attempt to cause a loss of faith in openweight models from China because for various reasons, China is where the majority of openweight models are coming
from. Again, watch my video about the labs being scared of Kimmy to better understand all of this. There's a lot of reasons that the Chinese labs are choosing to go openweight with their models, and China itself is definitely part of that strategy, but this post can and often was interpreted as an anti-openweight post, which is why everyone cooked him in the replies. I don't remember letting Anthropic scrape my GitHub profile as well as all of my online writing, citing the fact that Anthropic copied a lot of content from the internet, so why can't other labs copy from their work? Lol. Apparently,
the show still continues even when we're all aware of how you are fed these lines by anthropic funded lobbyists. Can you describe what distillation is to me? And of course, a personal favorite, given that Fable 5 refuses to do much of the tasks that Kimmy K3 does, I find this exceptionally hard to believe. Also, the fact that K3 came out just a few weeks after Fable went G again, there's no way they had enough data to do proper like distillation off of Fable. And now that I've used Opus 5 so much and have grown to hate it, I can say confidently that distilling Fable is not enough to make a
good model. So with all of that said and all of the comms around this catching fire, 2 days later, Jensen made this public letter. For my first post, I'm sharing a letter Nvidia signed on why open models matter. AI will transform every industry, power every company, and be built by every country. Open models strengthen safety and cyber security, accelerate innovation and diffusion, and enable sovereignty. The world needs both frontier closed models and frontier open
models. I'm so excited that Jensen is a believer in open source now. Looking forward to the CUDA and GPU driver open source release. Oh boy. And then we get the whole letter open weights and American AI leadership. This is a direct call out to the American government to not do anything stupid because there have been talks about potentially banning Chinese openweight models in the US which is really really bad. In the 1980s, early open-source software pioneers challenged the prevailing belief that software would advance only if companies kept tight control over
their code. This movement pushed for a transparent ecosystem where developers around the world could study, modify, and improve software. Software developed by the open-source community now supports most of the internet and underly systems used by the world's largest technology companies as well as the US military and federal agencies conducting scientific research, cyber security, and other critical missions. Open source did more than lower the cost of software. It created a shared foundation of knowledge on which generations of American engineers and entrepreneurs built their institutional
sovereignty. I say this a lot, open source is good for pretty much everyone. It makes it easier for businesses to be successful and compete. It makes it easier for nonprofits to have quality of software that is similar scales to that of like big wellunded businesses. Open source is great. It enables a much more level playing field for everyone who wants to put in the effort to play. And I love that. Back to the letter. The US now faces a similar choice with artificial intelligence. Our AI leadership will be judged not by one frontier AI model, but by whether the US
builds a strong and open ecosystem that diffuses into every sector. Interesting use of the word diffuses. that feel strategic. This is essential for creating opportunities for innovation and prosperity across the country. It requires expanding access to AI, encouraging competition, robust application layers, and giving Americans greater control over the technology that they rely on. Openweight models, Mdash, AI models that anyone can download, inspect, modify, and run on their own infrastructure, close mdash, are important parts of the foundation
because they make advanced AI more accessible, adaptable, and widely available. There's also an underline here that's not included, like a hidden between the lines piece here that openweight models give more people reasons to buy our chips. I also do actually like they put a definition of open weight so that they don't have to fight the whole but it's not really open source because remember Nvidia publishes actual open source models. They aren't just publishing the weights that they created. They're also publishing the data, the tools they use to train the models and everything you need to
recreate the model yourself. That is true open source. I don't think that matters that much in the world of models because nobody's going to spend millions on GPUs to recreate this from scratch themselves, but you can, which is cool. But they are not saying we're better cuz we're real open source. They're saying all openweight models matter and are trying to like advocate for that here. It is kind of ironic that Nvidia supports open source and openweight AI as much as they do though because they've historically been rough to the
open source world. >> So Nvidia, [ \_\_ ] you. Yeah, Nvidia has not supported things like Linux as well as they should have. Open Weights expanded access to the AI economy. Startups, established businesses, universities, and public institutions can build on advanced models without training one from scratch or paying frontier model prices for every task. Open Weights let every organization match the right model to the right job at the right cost, reserving frontier scale capability for genuine frontier problems and running
efficient specialized models everywhere else. I don't necessarily believe this is where we're actually going to go, but it is where a lot of businesses are now, so reasonable to put it in. That discipline is what will make AI economically sustainable as its use scales into the billions of everyday tasks. America wins the AI era by diffusing it into the workflows of factories, hospitals, farms, classrooms, and mainstream businesses. And the ability not to send all your data to anthropic or open AAI is worth calling out too. Open weights also strengthen competition and competition is what keeps the gains of AI broadly shared
rather than concentrated into a few hands. By allowing many orgs to build, adapt and deploy advanced models, open weights create rivalry not only among model developers but across cloud chips, applications and services. That competition spurs innovation, drives down costs and distributes the benefits of AI broadly across our economy. Open weights also give customers greater control. As orgs invest in AI, they want to know that they will not become locked into a single provider or lose the knowledge and capabilities that they build over time. Openweight models help provide that assurance by allowing organizations to control their own data,
evaluate and adapt models to their own needs, and deploy them whenever their business requirements demand. And as orgs create value with AI, open weights allow them to own that value through self-improving models, specialized capabilities, and accumulated knowledge that drive American sovereignty and prosperity. feel like they're using the word sovereignty a bunch here just to appease the current admin. And now we get to the security and safety section. To be sure, open weights carry real and distinct risks. Once released, the weights are beyond the original developers control and modified versions
are difficult to trace or reverse. I know a couple people at a couple labs that have been haunted by this in particular because normally when you're at OpenAI or Anthropic, you have a layer in between the model and the user that can filter things before the request goes in or the response goes out, which makes it a lot easier to protect. Once the weights are out there, you can't unrelease the files. People have them. So if you think that your model is incapable of doing anything really really dangerous like manufacturing
nuclear weapons or drugs and then it turns out somebody found a way to make it do that, you can't take that back. You can't remove that capability. The weights are out. And I know a lot of people who have struggled with this in particular, making sure that their testing is thorough enough that anything really dangerous isn't possible with the weights that they release. I also suspect this is part of the reason why the open weight releases for recent models have been delayed. things like K3 taking what was it like a week and a half from initial availability to the weights being public. That was because
they wanted to be extra sure that all of the risks were addressed. At least I would assume as much. Yeah, as they say in this letter, that is a real concern. You need to make sure that these weights don't have horrible capabilities before they are released. But the right response to this risk is not to prohibit open weights. In a world where cyber security attackers are using advanced AI, defenders need access to models with comparable capabilities so that they can detect, simulate, and respond to emerging threats, open models broaden defensive capability, increase transparency, and allow vulnerabilities
to be discovered and remediated across many teams. I used to not super love this point because I did kind of like the direction both Anthropic and OpenAI went with their whitelisted access programs for the companies building the foundations we rely on every day and the open source maintainers doing the same so that they could audit things like Windows and Mac OS and Linux. audit layers we rely on heavily, things like FFmpeg or OpenSSL, and find as many of these things as
possible early with unrestricted models from the major labs, so that when the more restricted versions come out or open weight versions come out that the likelihood that the these things can be poned goes down because they've been secured using the same technologies. I like the idea of early access to these capabilities going to the maintainers of the things that we all rely on. But we're now seeing the weird in between where things like the OpenAI hugging face hack occurred where OpenAI accidentally let GPT6 break out of an
isolated offline sandbox through multiple exploits. It found get into another sandbox with internet access and then route through that to pone external services like HuggingFace. And then when HuggingFace tried to use 56 to defend themselves, they got rejections and errors from the OpenAI APIs. And the same with Anthropics when they tried Fable. So they had to rely on an internal GLM52 instance that was unrestricted in order to defend themselves from GPT6. That's insane. Like it's happened. We have now crossed the threshold and the frontier labs are not providing enough access to enough
people with enough speed to keep themselves safe. So open weights as a in between protection method are effectively necessary now because the labs move too slow since anthropic and open AI didn't do enough with this early access program. We now have to lean on these open weight models to protect ourselves from even them which is kind of crazy. It's almost the thing OpenAI feared initially which is why I'm thankful that they're being reasonable about all of this. They're being reasonably supportive of openweight stuff and they even signed this letter.
The letter goes as far as saying that openness may be one of the most important paths to AI safety and security. Relying solely on closed models is not inherently safe. They can be breached, misused, or fail in ways that outsiders cannot detect. Yeah, we just saw all that. And concentrating advanced AI capabilities behind a small number of closed models compounds that risk. It results in a smaller number of single points of failure weakens competition and it leaves critical technology in the hands of just a few providers. OpenWeight models on the other hand allow a broad community of researchers and developers to examine their behavior, identify
vulnerabilities, develop safeguards, and improve them over time. Just as open- source software demonstrated that transparency can be more secure than obscurity, AI safety may depend on giving more people the ability to test and strengthen the models on which society relies. It allows for rigorous benchmarking and evaluation, red teaming, and protections tied to real and demonstrated harms rather than assuming that closed systems are safer by default. A strong AI ecosystem is not a foregone conclusion. Policymakers have an important opportunity to act. This includes expanding access to compute for
startups and researchers, investing in shared training assets like data sets, tools, evaluation frameworks, and more, and keeping the frontier plural by avoiding premature restrictions on open models that stifle competition or drive innovation overseas. These measures must also look at how strong application layers can expand sovereign use of AI across the economy. I do have to call out that this section feels kind of written to boost their sales because if you get the government to expand access to compute for startups and researchers,
they are getting the government to pay Nvidia for chips. If they invest in shared training assets like data sets, tools, and eval frameworks, more people are training models. And if they're training models, they're probably doing it on Nvidia. So, they're selling more as well. And if they prevent the restriction of openweight models, there are more companies that are trying to host these models that need NVIDIA chips. All of this is we want to sell more chips, but it is for the better of the technology. In shaping this ecosystem, policy makers should be careful not to conflate legitimate model
development techniques with misappropriation. Distillation or the practice of using one model's output to help train or improve others is a widely used technique for model improvement, eval, and validation. It reflects a long tradition of learning from, building upon, and improving existing technologies. a tradition that has helped drive innovation since the rise of the open-source software movement. By contrast, unlawful efforts to extract value from closed models raise legitimate concerns. Those concerns should be addressed through targeted
legal and commercial frameworks rather than sweeping restrictions on techniques that play an important role in AI innovation. This whole paragraph here is a very kindly worded middle finger to the policy makers and government officials that have been saying stupid things about banning openweight models because they're from China. This is them saying, "You're using that word distillation wrong. It's actually okay. Stop freaking out about this." And I'm happy they did that. The age of AI can be one of prosperity. With the right choices, openweight AI can expand opportunity, strengthen competition,
extend American technological leadership, mitigate risk, and ensure that the benefits of this technology are shared broadly across our economy. That future is worth building, and the United States should lead in building it. Yep, this last sentence I totally agree with. My American pride will show a bit here, but I do think we are the best home for AI. At least we should be now that we have these weird restrictions coming from the government and that is being combined with a potential anti-openweight policy. I would not be surprised if we see people starting to move somewhere like I don't know Canada.
America should be the place where this all happens. And it seems like a lot of companies agree and are petitioning to get the government to do the right thing here. Again, including OpenAI who signed this. So, let's see how the [ \_\_ ] Anthropic chose to defend themselves. Oh, wait. This is Microsoft publishing the same letter. Yeah, Microsoft themselves put the letter on their own website to make sure it was very clear by putting on the Microsoft corporate responsibility site
that this is their beliefs. So, let's see how Daario spins this one. Our position on open weights models. For what it is worth, there have been rumors at Anthropic that doing so much as mentioning openweight models in a positive light in your interviews could meaningfully affect the likelihood you were hired, which is crazy. I don't know how true those are cuz I don't have direct like first party accounts, but I've heard enough times that it would not surprise me. Over the last few days, there's been a lot of discussion about
openweight models, especially those from China. Reports suggest that some US officials are considering banning the use of Chinese openweight models by US companies. In response, many tech companies have signed a letter supporting openweight models. And some people have even accused Anthropic of wanting to ban openweight models as a means of protecting our business. I don't think you're necessarily doing it just to protect your business. I think you just have weird beliefs. But go off, king. Anyone who has read my past writing should know that I don't regard such bans as useful measures. But let me state it clearly so that there is no
doubt. Enthropic has never advocated for a ban on openweight models. Okay, so why haven't you signed openweight models that don't have dangerous capabilities are a public good? Oh, there we go. You don't want good openweight models in propic. They don't cost anything beside the compute needed to run them, and they provide values to businesses, developers, and researchers. Protectionist bands would not address Daario's most serious national security concerns. Specifically, he's worried about two nightmare scenarios. He laid them out in his essay, The Adolescence
of Technology, 6 months ago. He's held these positions consistently for many years. Scenario one is that his concern is the risk that authoritarian governments, not solely the Chinese Communist Party, although the CCP is clearly the most capable threat. He's concerned that they are building AI models that are more powerful than those built by the US, and that they can use them to achieve permanent military superiority or to perpetuate incredibly deep repressions of their own people. Concern is widely shared within the US government. Vice President Vance warned in Paris last year that authoritarian regimes have stolen and used AI to
strengthen their military intelligence and surveillance capabilities. And the intelligence community's 2026 annual threat assessment found that quote other global powers robust progress in AI is challenging US economic competitiveness and national security advantages. End quote. It is irrelevant whether these models are released with open weights and certainly irrelevant whether they are used by US businesses. In fact, the most dangerous model may be one that is trained in secret and handed only to the
People's Liberation Army for use in drones in the Ministry of State Securities for surveillance and repression. This is fair. I don't think this will happen simply because like it's so expensive to create these models and they have so much value outside of like private military use that that won't happen. But I get why you're concerned. It is hard for me to validate those concerns though because your complaint isn't about openweight models or these evil companies or these evil countries leapfrogging. Your biggest
complaint is distillation. You're not mad that they can get ahead. You're mad that they're catching up because you pulled the ladder up behind you. Anyways, let's hear the second concern. Dario's secondary concern is the risk that powerful AI models may be misused to carry out cyber attacks or biological attacks and that may have serious alignment problems. And I love that he specifically links the OpenAI hugging face article from Time about this, not the official OpenAI coms. He links to the time article here that is strategic.
That is a dig at his previous employer. Open weights models. There god there's how many M dashes are on this page? 38 M dashes. Okay, it's counting the non-M dash ones in open weights, but that's only 14 of them. Cool. So, that means there are 24 m dashes on this page. That's great. Anyways, maybe Daario is the reason that models like Mdash so much. Also, I hate the formatting here. Open weights models, it does not matter whether they come from China or anywhere else, do potentially present a higher
risk than closed models because it's very difficult to apply guard rails to them or monitor their usage. And once the weights are released, they cannot be withdrawn. Banning the use of these models by US businesses does nothing to address this risk because bad actors are unlikely to be legitimate US businesses. It would protect US AI companies from competition, but that has never been his goal. Okay, he called it out directly here. For what it is worth, I don't actually think Daario is scared of openweight models taking away his business or their success. I think he is
scared of people having access to good AI if it's not through Anthropic servers because he's genuinely so convinced he is the only one and his company's the only one doing it right and safe. We might end up in a weird position where Anthropic gets really close with the US admin and OpenAI slowly gets pushed out. I know Sam is currently in DC doing something so we'll see where that all goes. Here are the measures that Dario does support and he has continued to advocate for throughout his time at Anthropic. First, he says that we should not sell powerful chips or chipmaking equipment to China. And we also have to
crack down on the smuggling that has been going on. Links to a justice.gov site, the Office of Public Affairs, where there are people who are being charged, just three random individuals trying to divert high performance computer servers assembled in the US integrating sophisticated US AI technology to China. One was a US citizen, one was a Taiwanese citizen. Third person is still a fugitive, possibly at large. Interesting. Kind of crazy to link an article from March from the US government about three random people trying to sneak GPUs out of the
US, but sure. China has limited domestic production capacity and therefore due to the scaling laws cannot build more powerful models in the US without US chips. US chips that are manufactured at TSMC, by the way. Anyways, his next policy belief is that we should crack down on industrial scale distillation operations. Distillation is a much more compute efficient process than training models from scratch. crazy because you just did a big distillation pass on opus and didn't seem to work too great. It allows China to build much better models than its number of chips would
ordinarily enable and thus partially evade chip bands. Distillation does not allow the CCB to obtain equivalent or superior AI capabilities to the US, but it can bring the Chinese frontier to within a few months of the US frontier. Yeah, and I think that's totally reasonable and fine. It is true that many of the companies carrying out these distillation operations release openweight models, but the open weights are far less relevant than the fact that the operations are backed by an authoritarian state seeking to overtake the US at the frontier. We should have
policy interventions to deter this behavior. A blanket ban on openweight models is neither the correct remedy nor something that we have called for. Okay, so again, he is mad that they don't get to be the exclusive distillers of what they have built with Fable. On that note, I would highly recommend that everybody listening right now turn on permanent logging inside of their cloud code, codecs, cursor, and everything else and store all of those logs. If you use something like CLI proxy API, which I rely on heavily for all of my routing for cloud models, you can set up a flag
in it to store all of the logs of every request that comes in and out. So, if you hypothetically wanted to refine an open weight model to act more like Fable the way you used it, you can. And in a world where Enthropic is doing everything they can to lock this data down and prevent others from having it, you should do your best to keep your own because this might end up being much more important in the future with the direction things are going. His third request is that all sufficiently capable models, whether they're open or closed, should go through mandatory safety
testing. The best way to address the threats he is concerned about is to just directly test the models for cyber, biological, and alignment risks before release. This idea is pretty close to a consensus. He's been heartened both that the Trump admin has moved in this direction in recent months and by recent industry proposals that would apply such testing to the most capable models regardless of their country of origin whether they are open or closed while exempting less capable models such as those from startups in academia entirely. Also a good call out. No academic model with limited compute is going to be a real risk. Whether open
models do or don't pose an increased risk and whether the risk can be mitigated is something that should emerge from testing rather than be decided in advance. And there may be promising methods for improving the safety of open weights models, including recent research from AE Studio and Enthropic on modular training strategies. Note that to be effective, testing would need to be global, which means even the CCP would need to be on board. We'll talk about this in a follow-up video, too, because there's another letter that went out recently that has a lot of anthropic employees, open eye employees, and deepse employees
that all signed it. Now, Dario directly addresses the letter we read before. He claims he agrees with much of it. Open weights expand access to the AI economy. They strengthen competition at least for some use cases and they give customers greater control. Remember they weren't first, second, or even third place for doing reasoning. So it's funny because they advanced meaningfully thanks to the work of one of these openweight labs in China and now is saying that for at least some use cases that they are useful. Come on, man. Concerns about distillation should be addressed through
targeted legal and commercial frameworks, the same measures he described above. But he doesn't agree with the letter's assertions that open weight models necessarily make it easier to develop safeguards or that broad access to capabilities necessarily help defenders more than attackers. It seems at least as likely to him that the opposite will be true. For example, he worries that biology will have a strong attacker defender asymmetry where sufficiently capable models may be able to quickly weaponize a pandemic level virus with widely available materials. Whereas defense against these agents is
a multi-year operational task in the best case. Yeah, if they can make viruses faster than they can cure them, that would be really bad. He says that questions like this should be empirically answered by rigorous pre-release testing not assumed in advance. To summarize Dario and Enthropic's position, they have not and are not advocating for a ban on openweight models as a category. They should instead focus on keeping powerful chips out of authoritarian hands, stopping industrial scale distillation, and requiring safety testing of all sufficiently capable models, open and
closed. Come on. It's it's it's this last sentence is just so weird to read, man. It's like to analogize the sentence and how cringe it comes off to people who get what's going on. Developers should focus on making sure their applications are accessible, that all users of Apple computers are banned, and that their programs work when they're opened. One of those things is net positive for sure. One of those things is obvious, like, yes, we should all agree on this. And one of those things stuck in the
middle there and is really, really [ \_\_ ] stupid. They need to just get over this industrial scale distillation attack language. It's like the Y2K of the AI era. It just makes them look stupid. Is it a real problem? Perhaps some amount. But they've already done so much to reduce it. And the labs are still not just like catching up, but exceeding in some places. The fact that K3 could come out so close to Fable 5 and beat it in many ways shows that
these distillation attacks are not what is driving this success. It just makes them look petty and selfish to sneak that in here. If they had just ended this by saying we need to keep powerful chips out of authoritarian hands and make sure that all models are tested properly whether or not they're open, that's a great ending. Sneaking in this [ \_\_ ] distillation call out in the middle is so goddamn cringe. And whether or not they admit this here, that is the real thing they hate about this article.
the second to last paragraph here that calls out that distillation is a legitimate practice that is widely used for improving models and that it's reflecting a long tradition of learning from building upon and improving existing technologies. This is yeah like this is totally reasonable and anthropic is just making themselves look stupid by acting otherwise. If you're looking for the right moments to actually be scared of anthropic, the moment to know anthropics really changed and should be looked at differently is if a new openweight model
drops and is really good and is universally seen as really good and no official anthropic comm's channel mentions the word distillation for at least 2 weeks. The moment that happens, the moment Anthropic will shut the [ \_\_ ] up about distillation, that's when you know real change is happening at that company. And until then, they are a cult with a really powerful model. And I'm saying this as somebody who's currently running four $200 tier accounts because I love Fable so much. I like the model,
but I'm also realistic about the lab and what they do and what they do well and what they do poorly. And I hope that this helps you guys understand all of the sides here and come to your own conclusions. Are you going to be on the side that the vast majority of businesses that the vast majority of people in the AI world and even Nvidia, who I don't necessarily love, are on? Are you going to side with Anthropic because they really hate the concept of distillation being done by companies that are not themselves? I may have led you guys to a specific conclusion here, but it's your decision if you make that
conclusion or if you go against it. Curious how y'all feel. Leave some comments letting me know how you feel about open weight models, the government's involvement, and Anthropic's weird stance here. And until next time, peace nerds., Everyone Signed This Letter (...minus Anthropic), YouTube, 01kyskaw9rnmpwdnzttknap57a.